Raspberry Co-PI-lot (Part 9): What I Learnt Building It with an AI Agent

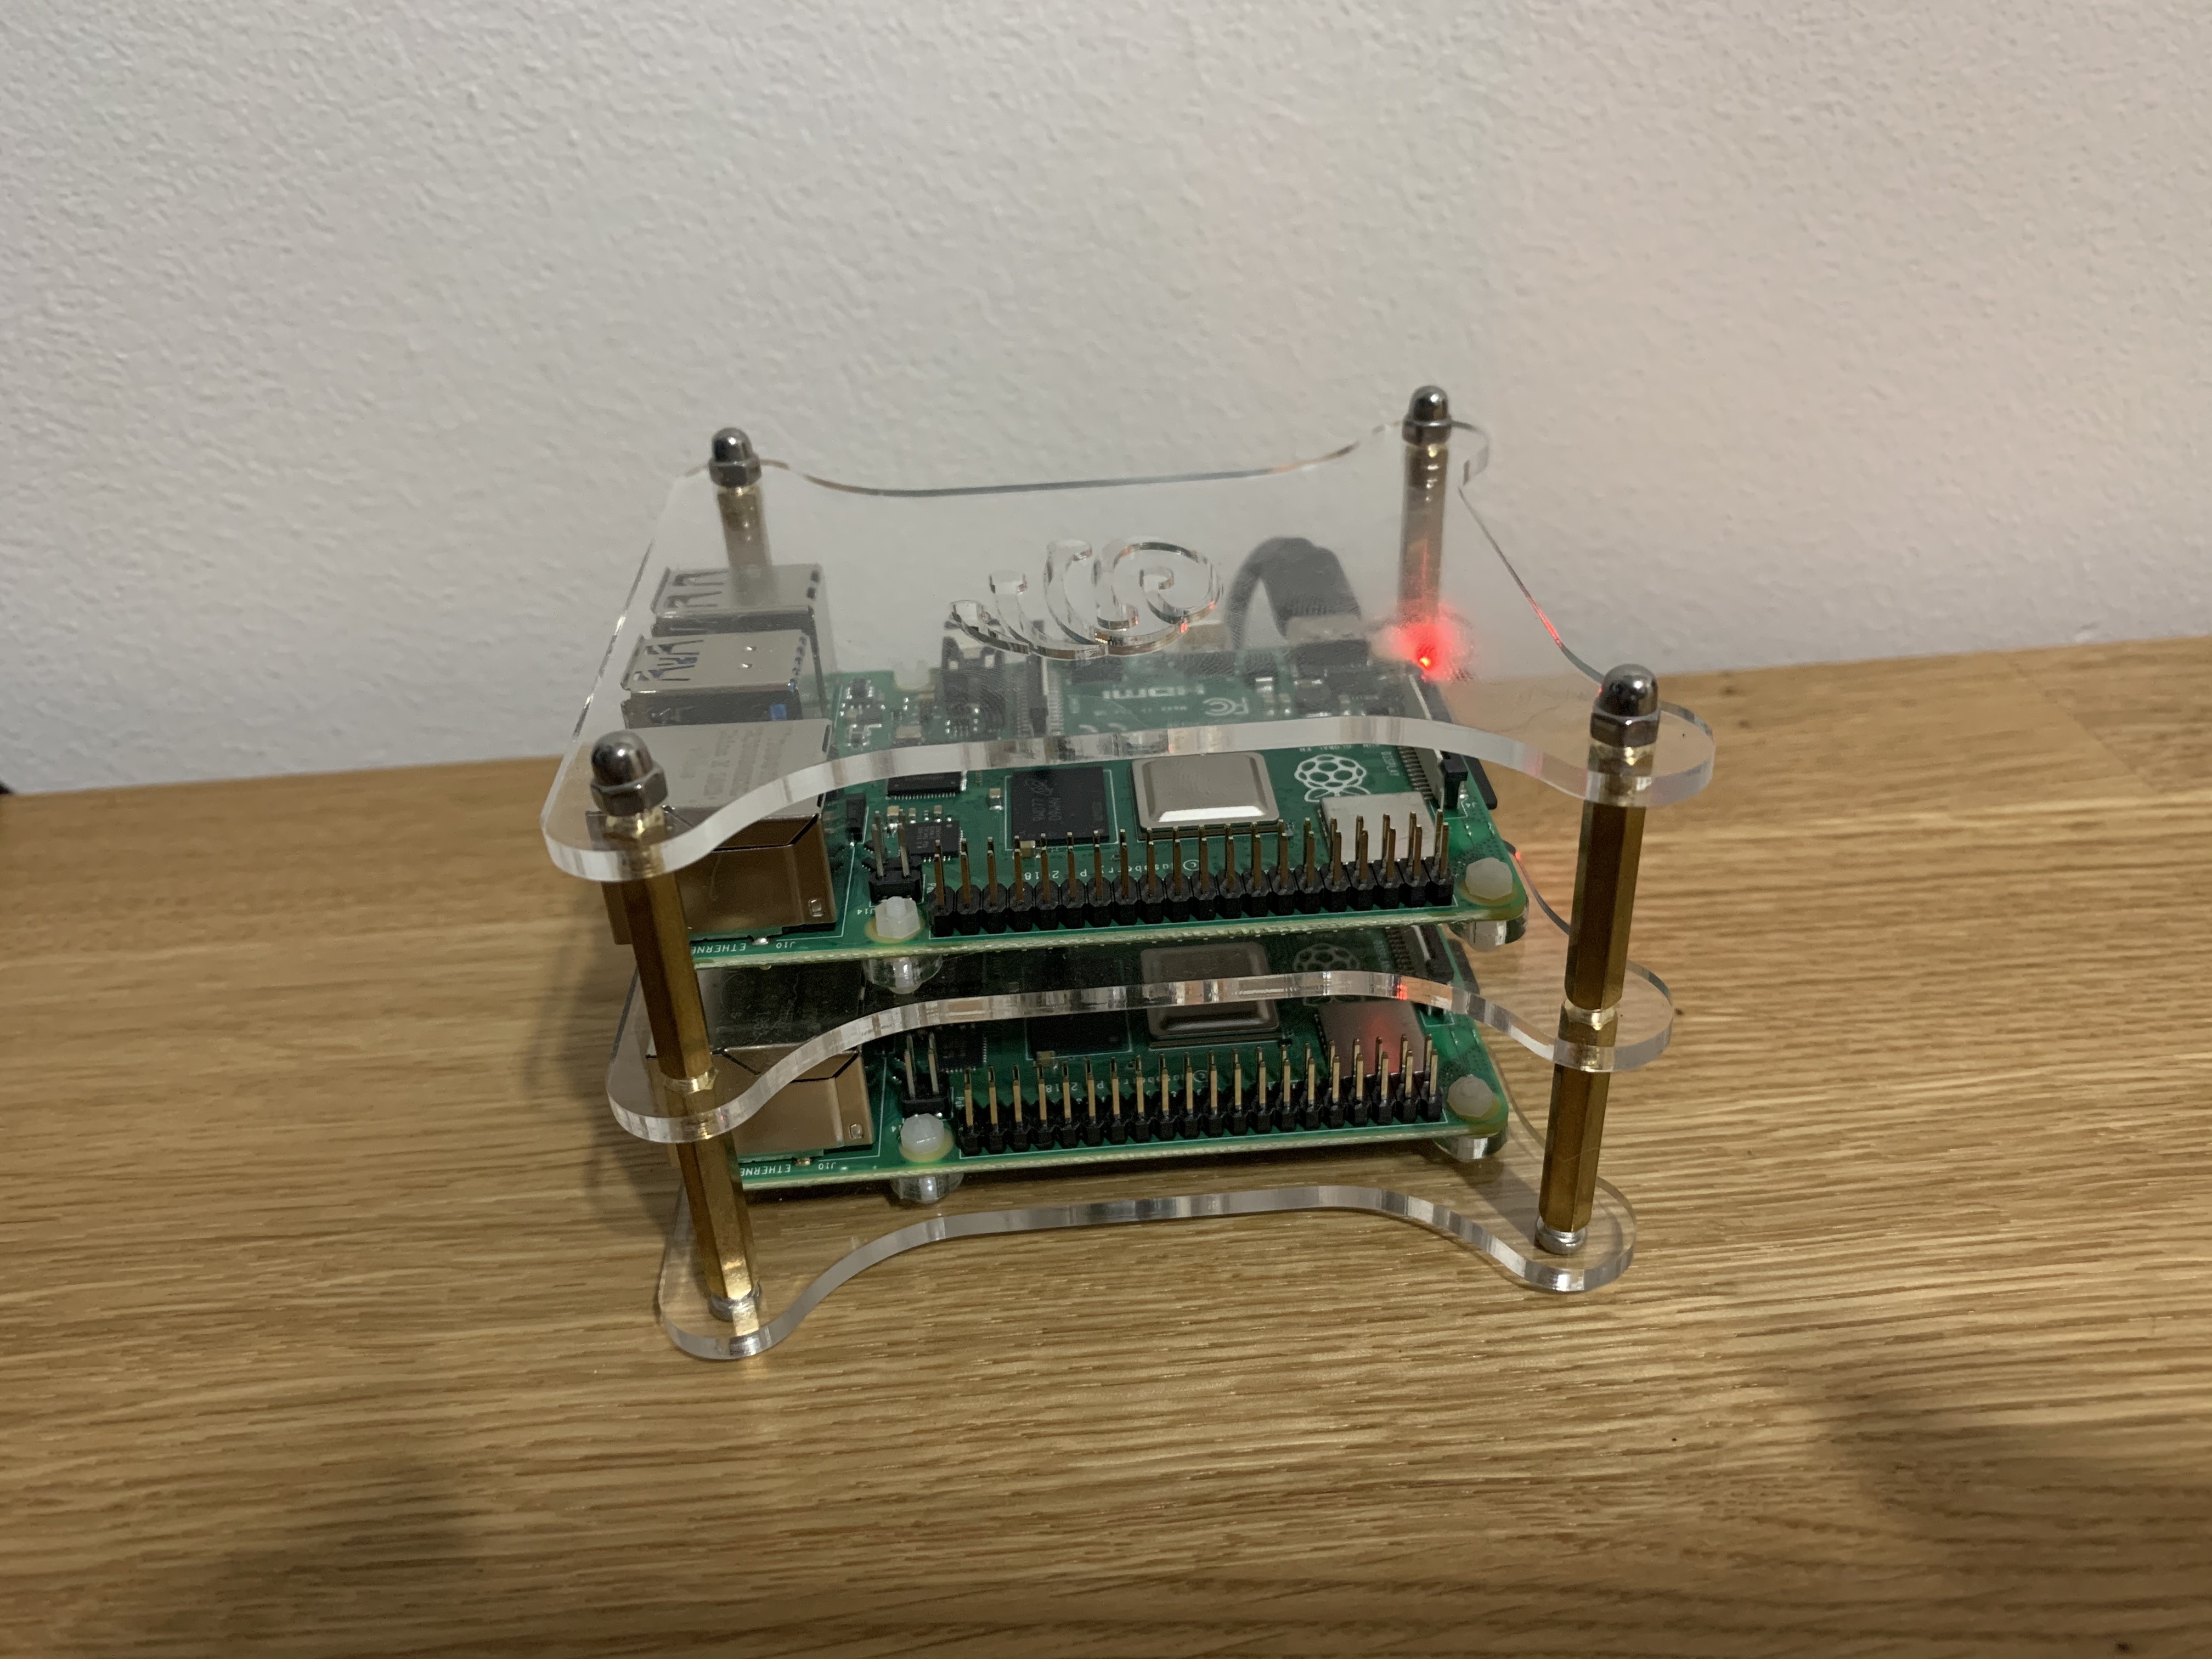
Recently I rebuilt the three Raspberry Pi cluster on my desk, and the whole platform took about a day. Git history says more than 60 commits between the evening of 15 November and the evening of 16 November 2026, with a sleep in the middle. I did not type most of the commands. An AI coding agent (omp, running Claude) did the typing, and I did the deciding.

This is the last post in the Raspberry Co-PI-lot series, a sequel to my 2020 Arc on Raspberry Pi post and my 2021 Okta and kubectl post. Parts 1 to 8 are listed at the bottom if you are joining late.

This post will cover how the work was split, the habits that made it safe, the mistakes (including one I would rather not talk about), and what I would tell a team doing infrastructure work this way. Let’s dive in!

How it actually worked

Think of a very fast, very eager junior engineer who never tires of SSH. I described what I wanted in plain English in a terminal on my Mac. The agent ran the commands on the Pis, wrote the manifests and the docs, committed and pushed.

I made the calls on scope, money, anything touching Azure, and policy questions. The agent asked before anything destructive or anything that cost money. For example, it did not get my sudo password. I enabled passwordless sudo on the nodes myself, and I accepted that risk knowingly rather than hand over a credential.

Research was the other big win. When I asked a question like "what are my options for a gateway in front of LLMs?", the agent fanned the work out to sub-agents. Each one wrote a cited report that landed in the repo under docs/research/. I got sources to click through instead of a confident paragraph from nowhere.

I also interrupted constantly, and that was a feature. A few of my favourites:

  • Mid-install of MicroK8s 1.30, because that was what the guide said: "if there is a more recent version of microk8s, we should be using that!" The agent purged it and installed 1.36.
  • When the agent proposed a 20 Gi volume: "try 10 unless you have a good reason to request 30% of my sdcard".
  • When it asked whether to switch a storage account to locally redundant storage: "GRS is fine, no need to swap to LRS".

None of those are clever. They are judgement calls that come from knowing what the thing is for.

What made it go well

A handful of habits did nearly all the work.

Git as the single source of truth

Once Flux was in place (Part 2), the rule became simple: change the repo, not the cluster. The agent’s work was reviewable as commits, and anything it did by hand showed up as drift. That beats scrollback in a terminal as an audit trail.

Written rules the agent actually reads

The repo has an AGENTS.md, a file of guidance for AI coding agents (and, as its own header says, a checklist for humans too). The hard rules in mine include things like:

  • Never commit plaintext secrets.
  • Node-level changes go one node at a time, with a health check between nodes.
  • Never re-run microk8s enable ingress, because it resets Traefik to defaults that cannot work on this kernel (Part 5).
  • No changes to Azure without my explicit request.
  • Verify after every change, and do not claim success without evidence.

Note: Almost every rule is a scar, written the moment something bit me so the next session would not repeat it. Rule 17, about the host firewall, is the one I like least, and I will come back to it.

Canary first, then everyone

Whenever a change touched the nodes (the proxy mode, the API server flags, the Entra config, the firewall), the agent started on one node, checked it and then did the others. With three-node dqlite, two down means no API, so this one was non-negotiable.

Test it, don’t believe it

The best moments were the boring tests. A baseline probe pod showed the router web UI, router DNS and node SSH all reachable from inside the cluster. After the network guard went in, the same probe showed them blocked while DNS and the internet still worked. Secrets encryption was proven by finding a marker secret in plaintext in the datastore files before and not after. Backups were proven by downloading the tarball and comparing hashes. The Key Vault half of my secrets setup was proven by decrypting with the age key deliberately missing.

In my opinion, that is the value. An agent that says "done" is worth nothing. An agent that says "done, and here is the probe that shows the before and after" is worth a lot.

What went wrong

The agent was wrong several times, and so was I.

The Calico crashloop

Part 6 has the full story, so here is the short version. I added a host firewall for the nodes. Every test passed: ports from my Mac, pods, a reboot of a node. Around seven hours later I noticed calico-node was crashlooping on every node.

I told the agent: "looks like calico is in a crashloop, I am fixing with another agent unless you tell me you caused it?" The reply was direct: "Yes, I caused it." The policy also applied to loopback, so Calico’s own liveness check against localhost:9099 was being dropped. The existing network dataplane kept working, which is exactly why every functional test passed. About 118 restarts per node had piled up.

The fix was one line, adding 127.0.0.0/8 to the allowed networks. The agent first checked the repo for changes from the other agent I had running, so the two did not trample each other. Then it watched calico-node for 14 to 16 minutes with no restarts.

The agent verified the things the change was meant to protect, and not the thing the change had touched. Restarts appear only after liveness probes start failing, so a check straight after rollout proves nothing. That is now a rule in AGENTS.md: after any firewall change, watch calico-node for 10 minutes.

Be warned: A confident "all checks passed" is only as good as the checks. I have made exactly the same mistake by hand, many times. The agent just made it faster.

The single sign-on dead end

I wanted the Bifrost dashboard behind Entra single sign-on (Part 8). The agent assumed that a proxy injecting an authentication header would be enough, and went down that path. When I tried it I saw a login prompt, not a proxied session. I told it exactly that: I was not seeing the proxy present the password, I was being challenged with a login prompt.

It turned out the dashboard only trusts its own session cookie and ignores the Authorization header. I decided to drop Entra and keep a password in Key Vault. That was a human call about what is good enough for a home lab, and I am comfortable with it. The wrong assumption was the agent’s, but the decision to stop digging was mine.

Small wrong things, caught by testing

A few smaller ones, because they add up:

  • The agent wrote a comment saying Traefik’s redirect was a 308. A real request showed 301, and it corrected the comment.
  • Research claimed the gateway could run without its SQLite store. Testing showed file-only mode crashes when budgets are on.
  • I had asked about the "18 month support window" for Kubernetes minor releases. The agent corrected me: roughly 14 months (12 plus 2), and it built the monthly version check around that.
  • A docs sub-agent wrote "verified" next to claims it had not verified. I had to send it back.
  • My laptop died twice mid-change. Each time the agent rebuilt its picture from git status, the cluster and Azure, and carried on. One of those was half way through the Bifrost revert: the Entra cleanup was done, the Key Vault delete had timed out and the manifests were uncommitted.

That last one is a good argument for Git and for infrastructure that can be inspected. State lived in the repo and the systems themselves, not in the agent’s head, so a restart cost minutes.

Where the human still matters

My view after this build is that the agent is fast at execution and decent at research, and it needs a person at the decision points. Mine were:

  • Money. The $100 cap on LLM spend (Part 8) was mine. So was keeping GRS storage when the agent asked whether to switch it to LRS.
  • Policy. Whether I could route my Claude subscription through a gateway was not a technical question. Research said Anthropic’s usage policy did not allow it, so I used a workspace API key and the plan’s included API credit instead. Read the terms yourself before you take an agent’s summary as legal advice.
  • Risk acceptance. Passwordless sudo and a break-glass admin certificate are trade-offs. I accepted them and wrote them down.
  • What "good enough" means. It is a lab on my desk. I want it patched and hardened, not a bank.
  • Noticing. I spotted the crashloop, not the agent. I had no alerting on it, and that is a gap I now know about.

The catch: an agent produces plausible, tidy-looking work quickly, and the polish can hide a wrong assumption for hours if nobody checks.

Food for thought for teams

If you are thinking about using an agent for infrastructure work, here is what I would take from my day:

  1. Put the state in Git and make the agent work through it. You get review, history and recovery for free.
  2. Write the rules down and keep adding to them. An AGENTS.md is cheap, and every incident is a new rule.
  3. Make it ask before it spends or deletes. Make the rule explicit, and keep Azure changes behind a human request.
  4. Demand evidence, not claims. Ask for the test, the before and after, and the hash comparison. Then ask what the change might have broken that the test does not cover.
  5. Watch longer than the probe period. Slow failures hide behind quick checks.
  6. Keep a human on money and policy. Those are the two things an agent cannot be accountable for.

None of that is new. It is just good change management for a very fast colleague. The agent compressed a lot of work into a day, but it did not remove the need for judgement. It moved the judgement to review time.

I would do it again, and next time I would write the "watch it for 10 minutes" rule before the incident.

Wrapping Up

Three Pis, more than 60 commits, roughly 24 hours, and about 2.8 GB of memory left per node with everything running. A good chunk of it was me saying "no, try this instead". Thanks for following along.

As always, feel free to reach out with any questions or comments!

The full series

This is the final part of the series. The full list:

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent (this post)

Until next time, stay cloudy!
Raspberry Co-PI-lot (Part 8): One LLM Gateway for Everything, with a Hard $100 Cap

Recently I realised every little project I touch wants an LLM, and each one wanted its own API key, its own billing and its own way to blow my budget at 3am. So I built one front door: an OpenAI-compatible endpoint on the cluster, virtual keys I hand out, and a spending cap I could actually trust. That last part is the interesting bit, because the cap is the thing most people hand-wave.

This post will cover running Bifrost on a Pi, keyless Azure AI Foundry models, friendly names, how Claude fits in (and why not my subscription), the layered $100 cap with real timings, and one honest dead end. Let’s dive in!

This is Part 8 of the Raspberry Co-PI-lot series. It leans on the keyless Azure access from Part 3 (Workload Identity Without AKS) and the pod-to-LAN guard from Part 6 (Hardening a Home Cluster, and How I Broke It).

Note: names, prices and policies are as I checked them in mid November 2026, and they move quickly.

In English Please?

Picture a hotel reception desk. Guests (my apps) never get the room keys (the model providers). They show a room card (a virtual key), and reception decides which rooms it opens and how much can go on the tab. If a guest misbehaves I cancel the card, not the master key.

Bifrost is that desk: an open source gateway with an OpenAI-compatible API that adds virtual keys, budgets and rate limits in front of whichever providers sit behind it. Callers point any OpenAI SDK at https://llm.lab.example.com/v1, use a virtual key as the API key and ask for a model by friendly name. It is reachable on my LAN and over remote access (Part 5) only.

Bifrost on a Pi

Bifrost runs as a Flux HelmRelease. Here is the sanitised core:

apiVersion: helm.toolkit.fluxcd.io/v2
kind: HelmRelease
metadata:
  name: bifrost
  namespace: llm-gateway
spec:
  interval: 1h
  releaseName: bifrost
  chart:
    spec:
      chart: bifrost
      version: 2.1.48
      sourceRef:
        kind: HelmRepository
        name: bifrost
        namespace: flux-system
  values:
    image:
      tag: v2.5.1
    replicaCount: 1
    resources:
      requests: { cpu: 100m, memory: 192Mi }
      limits: { memory: 384Mi }
    storage:
      mode: sqlite
      persistence:
        enabled: true
        storageClass: local-path
        size: 2Gi
      configStore: { enabled: true }
      logsStore: { enabled: true }
    extraEnv:
      GOMEMLIMIT: "300MiB"
    bifrost:
      sourceOfTruth: "config.json"
      client:
        disableContentLogging: true
        enforceAuthOnInference: true

Memory is tight on a 3.8 GB Pi, so the pod is capped at 384 Mi. Bifrost measured 167 Mi after start, peaking near 281 Mi. enforceAuthOnInference means every request needs a virtual key, and disableContentLogging keeps prompts and responses out of the logs. sourceOfTruth: config.json makes Git authoritative, so keys created in the dashboard vanish on the next restart.

Be warned: my plan was file-only mode, no database, no volume. Testing showed Bifrost exits with config store is required when governance (budgets and virtual keys) is on without a store, which matches an open upstream issue. So it gets a 2 Gi SQLite volume, which pins the pod to one node. When kured reboots that node the gateway is briefly down, so callers should retry.

Foundry with No Keys, and Friendly Names

For models I used an Azure AI Foundry account in Sweden Central. I prefer my data processed in Europe, and per the deployment types docs, a Data Zone deployment processes data only within the zone (the EU here). These are the four DataZoneStandard deployments, with the Data Zone prices I saw on the Azure meters at build time (per million tokens; check the pricing page for today’s):

Name Model In / out
mini gpt-6-luna $0.12 / $0.60
chat gpt-6.1-terra $1.20 / $6.00
open DeepSeek-V4-Flash $0.21 / $0.56
embed text-embedding-3-large $0.143

The Foundry Models sold by Azure page lists the GPT models, and notes GPT-6 tool calling wants the Responses API, or Chat Completions with reasoning_effort set to none. Qwen did not make the cut: the Qwen models in the catalogue were fine-tuning bases only, and hosting a tuned one would have cost roughly $219 a month.

No API keys, anywhere

The account has disableLocalAuth: true, so no API key exists to leak. Bifrost uses the Part 3 workload identity: a projected service account token federated to a managed identity holding only Cognitive Services User on this one account.

resource account 'Microsoft.CognitiveServices/accounts@2026-09-01' = {
  name: accountName
  location: 'swedencentral'
  kind: 'AIServices'
  sku: { name: 'S0' }
  identity: { type: 'SystemAssigned' }
  properties: {
    customSubDomainName: accountName
    allowProjectManagement: true
    disableLocalAuth: true
    publicNetworkAccess: 'Enabled'
  }
}

resource fic 'Microsoft.ManagedIdentity/userAssignedIdentities/federatedIdentityCredentials@2023-01-31' = {
  parent: uami
  name: 'cluster-llm-gateway-bifrost'
  properties: {
    issuer: oidcIssuer
    subject: 'system:serviceaccount:llm-gateway:bifrost'
    audiences: ['api://AzureADTokenExchange']
  }
}

On the Bifrost side an empty key value means "use the default Azure credential chain", which the Azure provider docs describe as DefaultAzureCredential. It is the cert-manager trick from Part 3: a projected token volume and three environment variables, no webhook.

Friendly names through routing rules

Nobody wants azure/gpt-6.1-terra in a config file. Bifrost routing rules evaluate a CEL expression and rewrite the target:

routingRules:
  - id: alias-chat
    name: alias chat
    enabled: true
    cel_expression: 'model == "chat"'
    scope: global
    priority: 1
    targets:
      - { provider: azure, model: gpt-6.1-terra, weight: 1.0 }

There is one per name, so swapping the model behind chat is a one-line Git change.

Claude, and Why Not My Subscription

I pay for Claude’s Ultra plan, and my first instinct was to expose that subscription through the gateway. The agent’s research said no.

Anthropic’s Usage Policy now lists, under "Do Not Abuse Our Platform": "Resell, proxy, or otherwise provide access to Claude through unauthorized means, including services that route requests through consumer subscriptions or misrepresent the product or client being used". The Claude Code legal page says developers building services should use Console API keys. In my opinion, risking my main Claude account for a convenience feature is a bad trade.

Thankfully there is a supported route: Max, Ultra and Team plans include a monthly API credit, $200 on Ultra. You link one Console organisation, the credit does not roll over, and it covers the API and Agent SDK but not interactive Claude Code. The line I cared about: with no purchased credit or auto-reload, "API requests stop until your next monthly credits arrive".

That is a vendor-enforced hard stop, so the Console organisation has no card and no auto-reload, the key sits in a workspace called gateway, and Bifrost exposes it as claude-fast, claude and claude-best. The pools are separate on purpose: the general virtual key cannot call Claude and the claude key cannot call Azure (I tested both), so one pool running dry never spills into the other.

The Cap, in Layers

Most cost caps are alerts wearing a trench coat. The Foundry cost docs say Azure OpenAI has no OpenAI-style hard limit and suggest action groups with custom automation. So I stacked layers and tested each with real traffic:

Layer Setting Measured
1. Bifrost budget $80 per calendar month Real time, 402 at the limit
2. Capacity TPM per deployment Caps burn rate, not total
3. Foundry cost control Block at $90 Enforced 10 to 15 minutes after spend
4. Tripwire over $15 per 24 hours pauses everything Refused calls about 3.5 minutes after trigger
5. Cost Management $100, emails at 50, 80, 100 percent Alerts only, lags up to 72 hours

Layer 1: why Bifrost overshoots

governance:
  customers:
    - id: capped
      name: capped
      budgets:
        - id: capped-monthly
          max_limit: 80
          reset_duration: "1M"
          calendar_aligned: true

Bifrost’s budget is check-then-charge, not a reservation. Its docs show a $2 request passing with $4 of $5 used, and only the next one refused. In a test against a mock backend, six concurrent $0.15 requests against a $0.20 cap all succeeded and charged $0.90. It is a soft ceiling.

Also, Bifrost prices at Global rates, so Data Zone spend (about 20 percent dearer for GPT-6) is under-counted. That is why the cap is $80, not $100.

Layer 3: Foundry’s cost control

Foundry has a preview cost control with a Block action. Be warned: the Bicep reference for costControls documents a rules-based shape on 2026-09-15-preview, while the call I used was on 2026-11-15-preview, which has no published Bicep types. This is what worked for me:

ACC=/subscriptions/<subscription-id>/resourceGroups/rg-<name>/providers/Microsoft.CognitiveServices/accounts/aif-<name>
az rest --method put \
  --url "https://management.azure.com$ACC/costControls/monthly-cap?api-version=2026-11-15-preview" \
  --body '{
  "properties": { "category": "Cost", "amount": 90, "timeGrain": "Monthly",
    "timePeriod": { "startDate": "2026-11-01T00:00:00Z", "endDate": "2027-12-01T00:00:00Z" },
    "providerProperties": { "actions": { "stop": { "type": "Block",
      "operator": "GreaterThanOrEqualTo", "thresholdType": "Percentage", "threshold": 100 } } } } }'

A temporary control with a $0.0001 limit, a fraction of a cent spent, and Azure began refusing every model with 429 budget_exceeded 10 to 15 minutes later. Deleting the control cleared it in about 3.5 minutes. That lag is Azure’s estimated cost catching up, the honest limit of this layer. The control ends on a fixed date (2027-12-01 in mine), so extend it before then.

Layer 4: the tripwire

Ten minutes suits a slow leak, not a runaway loop. A metric alert watches Foundry’s estimated cost over the trailing 24 hours and fires at $15 (normal pace is about $3.30 a day). It emails me and calls a Logic App that pauses every deployment:

pause_each: {
  type: 'Foreach'
  foreach: '@parameters(\'deployments\')'
  // One at a time: concurrent writes to deployments on one account return 409.
  runtimeConfiguration: { concurrency: { repetitions: 1 } }
  actions: {
    pause: {
      type: 'Http'
      inputs: {
        method: 'PATCH'
        uri: '@{concat(parameters(\'armUrl\'), substring(parameters(\'accountId\'), 1), \'/deployments/\', item(), \'?api-version=2026-09-15-preview\')}'
        headers: { 'Content-Type': 'application/json' }
        body: { properties: { deploymentState: 'Paused' } }
        authentication: { type: 'ManagedServiceIdentity', audience: environment().resourceManager }
        retryPolicy: { type: 'exponential', count: 6, interval: 'PT20S' }
      }
    }
  }
}

The concurrency: 1 line is a scar: the first test failed because pausing four deployments in parallel returned 409. After serialising it, a simulated alert paused all four and the gateway refused calls about 3.5 minutes later. Resuming took about 9 minutes. Resume is manual on purpose, because I want to know why it fired.

I rejected Azure API Management, at about $48 a month for the Developer tier (half the cap, spent on enforcing it). At full saturation (about $13 an hour) the 10 to 15 minute lag is worth a few dollars, so even a total Bifrost failure stops near $90, not the roughly $1,260 my research feared for billing-lag-only designs.

The Dashboard SSO Dead End

After Part 4 everything with a UI here signs in through Entra, so I asked the agent to put the Bifrost dashboard behind oauth2-proxy. On paper it worked: the proxy handled Entra and injected an Authorization: Basic header with the admin credentials, which Bifrost’s auth docs say works for API calls. Then Bifrost’s own login page appeared anyway.

I told the agent: "I am not seeing the proxy present the password, instead being challenged with a login prompt." On v2.5.1 of the open source edition, the UI trusts only its own session cookie (HttpOnly, called token, issued after a password login) and ignores an injected Basic header. Native OIDC sign-in is documented for Enterprise only.

My options were two logins for no gain, a CronJob faking the cookie, or a password. I picked the password and removed the proxy, redirect URI and client secret. A word from the wise: the admin API returns virtual key values, so that password is as sensitive as a provider key.

Working with the Agent

I made the calls on scope, money and policy; the agent did the research, Bicep and testing. My opening ask was one paragraph: Bifrost as a general gateway, Foundry in a new resource group, a $100 token maximum unless I exempt something, Europe preferred, and use my Claude plan’s credit. The agent fanned research out to sub-agents that wrote cited reports, catching the file-only crash, Qwen being unusable, the overshoot and Anthropic’s policy change four days earlier.

It got right what mattered most: testing claims instead of trusting them. The 10 to 15 minute lag and the 3.5 minute tripwire are measurements, and it diagnosed the Logic App 409s itself.

It got the SSO assumption wrong (I spotted the login prompt). I also pasted a user-scoped Anthropic key that needed an extra workspace header, so I made a workspace key, which the agent validated without printing it. Whether to touch my subscription at all was my call.

My laptop also died mid-revert of the SSO attempt, with the Key Vault delete timed out and manifests uncommitted. The agent rebuilt the state from git status, the cluster and Azure, and finished the job.

Wrapping Up

One endpoint now serves everything at home, with keyless Azure access, a vendor-enforced stop on Claude and five layers of cap I have timed rather than assumed. Next is the capstone on what building all this with an AI agent was actually like.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap (this post)
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 7): Keeping It Patched Without Babysitting It

Recently I did something slightly embarrassing: I flashed the desktop image. When I rebuilt the cluster I grabbed the standard Raspberry Pi OS, and it came with a full graphical desktop, browsers and all, on three headless boxes in a cupboard. On a 4 GB Pi, that is a rather expensive hobby.

I only found out because I asked the cluster to patch itself. The first run wanted 151 packages, and the dry run sat for about 28 minutes chewing on desktop package templates (chromium, firefox and friends).

This is Part 7 of the Raspberry Co-PI-lot series. Earlier parts cover the rebuild, GitOps and secrets, workload identity, Entra ID for kubectl, ingress and certificates, and hardening. The full list is at the bottom.

This post will cover turning three desktops into headless nodes, patching the OS automatically with unattended-upgrades and kured, the Raspberry Pi kernel quirk that looks like a bug but isn’t, how I handle Kubernetes minor upgrades, and the day I discovered my distribution had stopped moving. Let’s dive in!

Removing the Desktop

Think of heating a three-bedroom house when nobody is home. The desktop cost about 0.5 GB of resident memory per node for a login screen nobody would ever see, and with 3.8 GB per node that is a big chunk.

I told the agent I wanted a console-only setup and the desktop gone. It wrote a script that does three things. It lists the packages that must never be removed (networking, SSH, snapd, the kernel packages, cloud-init and the patching tooling). It builds a purge list by pattern (desktop metapackages, display manager, compositors, audio, browsers, VNC). And then it simulates the purge and aborts if the plan would touch anything on the protected list.

# Mark keepers manual so autoremove can never take them (also in --dry-run: it only changes apt's
# auto/manual flags, which makes the simulated plan accurate), then check the full plan first.
apt-mark manual "${installed_keep[@]}" >/dev/null
plan=$(apt-get -s purge --autoremove "${remove[@]}" | awk '/^Purg /{print $2}')
for p in "${installed_keep[@]}"; do
  if grep -qx "$p" <<<"$plan"; then echo "ABORT: plan would remove protected package $p" >&2; exit 1; fi
done
echo "plan: $(wc -l <<<"$plan") packages to purge; no protected package affected"

The script is run one node at a time over SSH, dry run first, then for real with systemctl set-default multi-user.target, followed by a drained reboot. About 860 packages went in the bin per node, and available memory went from roughly 2.3 GB to between 2.8 and 2.9 GB.

Note: Marking the keepers manual first is the clever bit. On a Wi-Fi-only Pi, an autoremove that takes NetworkManager or the Wi-Fi firmware means a trip to find a keyboard and a monitor.

Patching: One Part Installs, One Part Reboots

I asked the agent a question I’d recommend asking yourself: "does kured also cater for OS upgrades? those need to be included". The answer is no. kured only reboots nodes; it has no idea how to install anything. So there are two halves: unattended-upgrades installs the packages, and kured reboots when needed.

Here is the unattended-upgrades policy on each node. It allows Debian’s release, updates and security origins, plus the Raspberry Pi Foundation’s repository (that is where the kernel and firmware come from), and it is told never to reboot on its own.

Unattended-Upgrade::Origins-Pattern {
        "origin=Debian,codename=${distro_codename},label=Debian";
        "origin=Debian,codename=${distro_codename}-updates,label=Debian";
        "origin=Debian,codename=${distro_codename}-security,label=Debian-Security";
        "origin=Raspberry Pi Foundation,codename=${distro_codename}";
};
Unattended-Upgrade::Automatic-Reboot "false";
Unattended-Upgrade::Remove-Unused-Kernel-Packages "true";
Unattended-Upgrade::Remove-Unused-Dependencies "true";
Unattended-Upgrade::SyslogEnable "true";
Dpkg::Options {
        "--force-confdef";
        "--force-confold";
};

The Dpkg::Options block keeps my existing config files when a package ships a new one, so no run stalls on a prompt nobody will answer.

To make sure all three nodes never run an upgrade at the same moment, each has a timer override with its own time (06:00, 06:40 and 07:20 Sydney time). A NetworkManager restart on all three at once could cost me dqlite quorum, so staggering is cheap insurance.

[Timer]
OnCalendar=
OnCalendar=*-*-* 06:00
RandomizedDelaySec=0
Persistent=true

Then kured, deployed by Flux as a Helm release. Here are the values that matter:

values:
  configuration:
    period: 30m
    rebootDays: [mo, tu, we, th, fr, sa]
    startTime: "2:00"
    endTime: "5:00"
    timeZone: Australia/Sydney
    concurrency: 1
    lockTtl: 1h                  # free a lock held by a node that never came back
    lockReleaseDelay: 10m        # let dqlite and pods settle before the next node reboots
    drainTimeout: 10m
    forceReboot: false           # if a drain can't finish, skip the reboot rather than force it
    skipWaitForDeleteTimeout: 60
    annotateNodes: true

In plain English: every 30 minutes each kured pod checks for /var/run/reboot-required. If it exists, and it is between 02:00 and 05:00 Monday to Saturday, the node takes a cluster-wide lock, drains, and reboots. Only one node can hold the lock (concurrency: 1), and after each reboot it waits ten minutes before letting the next one go. The window dodges the backups from Part 3 and the Sunday snap refreshes from Part 1.

A word from the wise: forceReboot: false is a deliberate choice. If a drain cannot finish, I would rather skip tonight’s reboot than force one and risk taking a second node’s workloads down. kured’s defaults are far more relaxed (any day, any time), so tighten them if you have a quorum to protect.

The Kernel That Is "Kept Back"

Here is the quirk that made me squint. Raspberry Pi kernels arrive under new package names (for example linux-image-6.18.60+rpt-rpi-v8), rather than as an upgrade to an existing package. A plain apt-get upgrade never installs new packages, so it reports the kernel as "kept back" and walks away.

unattended-upgrades does not have that limitation. When I ran unattended-upgrade -v by hand on node 3, it moved the node from kernel 6.18.50 to 6.18.60 and created /var/run/reboot-required, the signal kured waits for. If you patch by hand, use unattended-upgrade -v (same policy as the timer) or apt-get full-upgrade.

This matters more on my cluster than most. Back in Part 1 the 6.18 kernel had no legacy ip_tables module, which is why kube-proxy runs in nftables mode. A new kernel could, in theory, change that. So I rebooted node 3 onto the new kernel by hand as a canary: still no ip_tables, kube-proxy still in nftables mode, node healthy. The other two follow via kured.

Be warned: on one node, installing unattended-upgrades triggered its own run, which held the dpkg lock. My catch-up run did nothing, and then a reboot interrupted the first run halfway. Re-running fixed it, but give a fresh node a few minutes before fighting apt for the lock.

Kubernetes Minor Upgrades

OS patches are the easy half. Kubernetes itself moves a minor version roughly every four months, and I told the agent the support window was 18 months. It corrected me: the Kubernetes project supports each release for roughly 14 months, 12 of standard support plus a two-month maintenance tail. Staying one minor behind is comfortable; two gets tight.

Patch releases arrive through snap refreshes on the pinned track (staggered per node, as in Part 1). Minor upgrades I kept deliberately manual but well gated, in two pieces.

A monthly check, in GitHub Actions. A scheduled workflow runs a script that compares my pinned track against the MicroK8s snap store and the support dates on endoflife.date. When something needs doing, it opens (or updates) a single issue labelled k8s-upgrade. When nothing is needed, it closes it. It never touches the cluster, and it does not run on my laptop, which is rather the point.

Its policy:

  1. Never skip a minor.
  2. Upgrade once MicroK8s publishes the next track for arm64 at patch .2 or later, so someone else finds the early bugs.
  3. Finish before the current minor leaves standard support; warn 120 days ahead.
  4. Flag MicroK8s itself if its build is behind upstream patches for more than 60 days.

A gated upgrade script. It has a --dry-run mode that runs every gate and changes nothing: target is exactly the next minor, the new track exists, the cluster is healthy, no client is still calling APIs removed in the new version, the repo manifests pass kubeconform for the new version, and a fresh dqlite backup has just been uploaded. For the real run it goes node by node (03, then 02, then 01, because 01 is my default API endpoint): drain, snap refresh, wait for Ready at the new version, then check that the custom API server and kube-proxy arguments from Parts 4 and 6 survived. If anything fails, it stops with that node cordoned and the other two keep quorum.

The Surprise: MicroK8s Has No 1.37

The first run of the monthly check found something I did not expect. Upstream Kubernetes 1.37 was released on 26 August 2026. On 16 November, nearly three months later, MicroK8s had no 1.37 track at all. The issue tracker explains why: a build failure on master because the kubelite patch set only went up to 1.36.

Worse, the 1.36/stable channel was sitting at v1.36.2 when upstream was at 1.36.6, four patch releases behind. That is what I saw on the day; check the channels yourself, as it will have moved.

Not a deal breaker for a home lab, but it changed how I think about the distribution choice. A distribution that bundles Kubernetes, dqlite and add-ons gives you HA in an afternoon, but you inherit its release cadence, and upstream fixes only reach you when it rebuilds. That is precisely why the check script flags MicroK8s lagging as its own action item, separate from the upgrade being due. In my opinion that is a trade-off to understand before you pick, rather than discovering it three months in.

The Schedule That Switches Itself Off

One small gotcha. GitHub’s documentation says that in a public repository, scheduled workflows are automatically disabled when there has been no repository activity for 60 days. My cluster repo is quiet by design. A monthly check that silently turns itself off is a very Raspberry Pi sort of failure.

My first idea was a trivial commit-and-delete now and then. The agent went with something tidier, a first step in the workflow that re-enables the workflow through the API, with no commits needed.

- name: Keep schedule alive
  run: gh api -X PUT "repos/$GH_REPO/actions/workflows/k8s-version-check.yml/enable"

It runs first, so a later failure in the job cannot skip it, and the workflow needs actions: write permission for it. To be straight about it: the 60-day rule is documented for public repos and mine is private, and I have not tested whether the enable call actually resets the timer. It costs nothing, so it stays.

Working with the Agent

My co-pilot did the typing; I did the steering. Some moments:

  • I asked the right question, and it gave the right answer. "Does kured also cater for OS upgrades?" The agent explained that kured only reboots, installed unattended-upgrades alongside it, and kept major Debian releases as a manual runbook because a new release changes the kernel, systemd, NetworkManager and snapd together.
  • It noticed the desktop, I made the call. The slow dry run was the clue. The agent worked out that the nodes were running the full desktop, and I chose "console + remove desktop packages". It then wrote the protected-package dry run, which I would not have thought to ask for.
  • It was wrong about my own number. I said Kubernetes had an 18-month support window; the agent corrected me to about 14 months, and the policy in the script follows the real figure.
  • It admitted a gap. I asked whether the monthly check ran on the laptop (it runs on GitHub’s runners), then worried about the 60-day disable. The agent built the keepalive and was upfront that the documented rule covers public repos while mine is private.

Wrapping Up

Three Pis now patch themselves overnight, reboot one at a time, and tell me by GitHub issue when Kubernetes needs a decision. The only manual jobs left are the ones that deserve a human: minor Kubernetes upgrades and new Debian releases. Next up: an LLM gateway with a hard cost cap.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It (this post)
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 6): Hardening a Home Cluster, and How I Broke It

Recently I asked my co-pilot a question I already suspected the answer to. It was around nine at night, and the Calico pods on every node were sitting in a crashloop with over a hundred restarts each. I typed: "looks like calico is in a crashloop, I am fixing with another agent unless you tell me you caused it?"

The reply was four words long: "Yes, I caused it."

I have had worse confessions from humans. This one at least arrived with a fix. But what stuck with me is that everything had passed. Port scans from my Mac, pod tests, even a drain and reboot of one node. Roughly seven hours later the network layer had restarted about 118 times on each node, and none of my tests had noticed.

This is Part 6 of the Raspberry Co-PI-lot series. Earlier parts covered rebuilding the cluster, GitOps with Flux and SOPS, workload identity, Entra ID for kubectl and ingress with certificates. Each one is listed at the bottom, none of them required, but the identity and ingress posts are the ones this post leans on most.

This post will cover the hardening I put on the cluster (Pod Security Admission, network policies, a LAN guard, Secrets encryption, audit logging and a host firewall), the single line that broke it, and what hardening with an AI agent was like. Let’s dive in!

Why Bother Hardening a Home Cluster?

Three Pis on my desk, behind a router, with no public ingress. But the threat I care about is me running something dodgy in a container one day, and it then poking around my home network. Think of a block of flats: no burglars in the lobby, but every flat still gets a lock and the fire doors stay shut.

The goals were modest: make a compromised pod boring, keep it off the LAN, keep stolen backups useless, record who changed what, and shrink what each node listens on. Memory is tight here (3.8 GB per Pi), so it had to be configuration, not software.

Pod Security Admission and Network Policies

Kubernetes ships with Pod Security Admission, which checks every pod against one of three Pod Security Standards: privileged, baseline or restricted. You turn it on per namespace with labels, and I put one on every namespace. Most are restricted. Three are privileged on purpose, because Calico, kured and the local-path helper pods need host access.

For namespaces I forget to label, the API server also takes a cluster-wide default from an admission configuration file. This is the block I added on each node:

apiVersion: apiserver.config.k8s.io/v1
kind: AdmissionConfiguration
plugins:
  - name: EventRateLimit
    path: eventconfig.yaml
  - name: PodSecurity
    configuration:
      apiVersion: pod-security.admission.config.k8s.io/v1
      kind: PodSecurityConfiguration
      defaults:
        enforce: baseline
        enforce-version: latest
        audit: restricted
        audit-version: latest
        warn: restricted
        warn-version: latest
      exemptions:
        usernames: []
        runtimeClasses: []
        namespaces: []

MicroK8s already ships this file with EventRateLimit, so I added PodSecurity beside it. An unlabelled namespace now enforces baseline and warns about anything that would fail restricted. The shape follows the Kubernetes docs for enforcing standards cluster-wide. A privileged pod in a fresh namespace was refused, which is all the testing it needed.

Enforcing restricted meant my whoami canary and the Zot registry had to run as non-root. Zot’s volume had to be recreated, because local-path volumes are plain host directories and fsGroup does not chown them.

Next, NetworkPolicies. Each app gets a default-deny for ingress and egress, plus an explicit allow from Traefik. Here is the whoami pair:

apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: default-deny
  namespace: whoami
spec:
  podSelector: {}
  policyTypes: [Ingress, Egress]

A matching allow-from-traefik policy lets only Traefik reach port 8080. A pod in default now times out against the Service, but still reaches the app through https://test.lab.example.com. Note: once egress is default-denied, a pod that needs DNS needs an explicit allow to CoreDNS on port 53.

Keeping Pods Off My Home Network

This was my own ask: pods may reach the internet, but not the router, other devices or the nodes’ management ports.

First I measured. A throwaway busybox pod could reach the router’s web UI and DNS, SSH on a node and the MicroK8s cluster agent. Not a great baseline.

Plain NetworkPolicy is awkward for "everything private except a few things", so I used Calico. A Calico tier is evaluated before namespace NetworkPolicies, which makes it a good place for a cluster-wide guardrail:

apiVersion: crd.projectcalico.org/v1
kind: Tier
metadata:
  name: lan-guard
spec:
  order: 500
  defaultAction: Pass
---
apiVersion: crd.projectcalico.org/v1
kind: GlobalNetworkPolicy
metadata:
  name: lan-guard.block-private-egress
spec:
  tier: lan-guard
  order: 100
  selector: has(projectcalico.org/namespace)
  types:
    - Egress
  egress:
    - action: Pass
      protocol: TCP
      destination:
        nets: [192.168.1.101/32, 192.168.1.102/32, 192.168.1.103/32]
        ports: [16443, 10250]
    - action: Pass
      protocol: UDP
      source:
        selector: k8s-app == "kube-dns"
      destination:
        nets: [192.168.1.1/32]
        ports: [53]
    - action: Pass
      protocol: TCP
      source:
        selector: k8s-app == "kube-dns"
      destination:
        nets: [192.168.1.1/32]
        ports: [53]
    - action: Deny
      destination:
        nets: [10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16, 100.64.0.0/10, 169.254.0.0/16]
        notNets: [10.1.0.0/16, 10.152.183.0/24]
    - action: Pass

(The node IPs are placeholders. The pod and Service ranges are the MicroK8s defaults.)

Top to bottom: pods may reach the API server and kubelet, CoreDNS may forward to the router, everything else private is denied except our own pod and Service networks, and the rest passes on to later tiers. The first exception looks odd until you know that Calico sees API traffic after kube-proxy rewrites the destination, so it appears as a node IP on port 16443.

After applying it, the router, node SSH and cluster agent all timed out from a pod, while the API, DNS, Services and the internet still worked. Remember that has(projectcalico.org/namespace) selector; it matters in a minute.

Encrypting Secrets and Logging Who Did What

By default Kubernetes stores Secrets unencrypted, and the dqlite backups from Part 3 would carry them too. The Kubernetes docs on encrypting data at rest list the provider options. I picked secretbox, which the docs describe as using XSalsa20 and Poly1305 and as faster than the others with a 32-byte key. They list KMS v2 for external key services, and note that secretbox key material is accessible from the control plane host.

That matters here. I generated the key straight into Key Vault (kv-<name>) and a script pipes it over SSH into a root-only file on each node. So this protects the datastore files and backups, not against root on a node. For a home cluster I am fine with that.

The rollout order matters. Every API server must read a format before any writes it, so the config goes in twice:

# Step 1, "read" mode: still writes plaintext, but can decrypt secretbox.
apiVersion: apiserver.config.k8s.io/v1
kind: EncryptionConfiguration
resources:
  - resources: [secrets]
    providers:
    - identity: {}
    - secretbox:
        keys:
          - name: key-2026-11-16
            secret: <32-byte key, base64, from Key Vault>

In step 2 the order flips, with secretbox first so new writes are encrypted. I restarted one API server at a time between steps, then rewrote every Secret with kubectl get secrets -A -o json | kubectl replace -f - (24 of them). A marker Secret was findable in the dqlite files in plaintext before, and not after.

A word from the wise: losing that key makes every Secret unreadable, and a restore needs it. Key Vault holds the only copy, with purge protection on.

Audit logging is the quiet one. The policy works at Metadata level only (the Kubernetes audit docs explain that this logs who, when, what and which verb, but not request or response bodies), so Secret values never reach the log. It records every create, update, patch and delete by anyone, plus who read a Secret, and drops reads, watches, events, leases, health checks and the control plane’s own chatter:

apiVersion: audit.k8s.io/v1
kind: Policy
omitStages:
  - RequestReceived
rules:
  - level: None
    resources:
      - group: coordination.k8s.io
        resources: [leases]
      - group: ""
        resources: [events]
      - group: events.k8s.io
        resources: [events]
  - level: None
    userGroups: ["system:nodes"]
  - level: None
    users:
      - system:kube-scheduler
      - system:kube-controller-manager
      - system:kube-proxy
      - system:apiserver
  - level: None
    nonResourceURLs: ["/healthz*", "/livez*", "/readyz*", "/version", "/metrics", "/openid/*", "/.well-known/*"]
  - level: Metadata
    resources:
      - group: ""
        resources: [secrets]
    verbs: [get, list]
  - level: Metadata
    verbs: [create, update, patch, delete, deletecollection]
  - level: None

The log lives outside the snap at /var/log/kube-apiserver, about 60 MB per node at most. A ConfigMap I created and deleted as my Entra user showed up with my username. Be warned: it is per node, not shipped anywhere and nothing alerts on it. It is a record, not a defence.

The Host Firewall, and the Line I Forgot

The nodes themselves, last. First I shrank what they listen on: rpcbind and avahi-daemon masked, controller-manager and scheduler bound to localhost. Then a firewall. Calico can do this without another daemon: host endpoints represent a node’s own interfaces, and policy can then apply to traffic into the node. Calico can create them automatically.

The design: the LAN reaches only SSH (22), the Kubernetes API (16443) and Traefik (80 and 443), plus ICMP. Everything else (kubelet, dqlite, the cluster agent, VXLAN) comes only from the three nodes and the pod network. Calico also has failsafe rules so a mistake cannot cut off every host, and I listed SSH and the API port there explicitly.

The policy today:

apiVersion: crd.projectcalico.org/v1
kind: FelixConfiguration
metadata:
  name: default
spec:
  failsafeInboundHostPorts:
    - { protocol: tcp, port: 22 }
    - { protocol: tcp, port: 16443 }
    - { protocol: udp, port: 68 }
---
apiVersion: crd.projectcalico.org/v1
kind: KubeControllersConfiguration
metadata:
  name: default
spec:
  controllers:
    node:
      hostEndpoint:
        autoCreate: Enabled
---
apiVersion: crd.projectcalico.org/v1
kind: Tier
metadata:
  name: host-firewall
spec:
  order: 400
---
apiVersion: crd.projectcalico.org/v1
kind: GlobalNetworkPolicy
metadata:
  name: host-firewall.node-ingress
spec:
  tier: host-firewall
  order: 100
  selector: has(kubernetes.io/hostname) && !has(projectcalico.org/namespace)
  types: [Ingress]
  ingress:
    - action: Allow
      source:
        nets: [127.0.0.0/8, 192.168.1.101/32, 192.168.1.102/32, 192.168.1.103/32, 10.1.0.0/16]
    - action: Allow
      protocol: TCP
      destination:
        ports: [22, 16443, 80, 443]
    - action: Allow
      protocol: ICMP
    - action: Deny

First, remember the lan-guard selector? It started life as all(). With host endpoints about to exist, all() would have matched the nodes too and cut them off from the router and each other, so I narrowed it to pods only before rolling out the firewall. That was the agent’s call.

Second, I rolled out carefully: canary on node 3, then the rest. From my Mac, ports 22, 16443, 443 and 80 were open and 10250, 19001 and 25000 blocked on every node. A drained node rebooted with the firewall active and rejoined. All green by about two in the afternoon.

Now look at the first line of nets: 127.0.0.0/8. That line was not in the original. The auto host endpoints cover every interface, including loopback, so the final Deny dropped localhost traffic. Calico’s own liveness check (calico-node -felix-live, which calls localhost:9099) timed out and Kubernetes kept restarting the pod.

Why did every test pass? The existing dataplane kept forwarding traffic, so pods ran, ports were blocked correctly and a reboot worked. The thing I had changed was failing in the one place I was not watching, and restarts only appear after the first failed probes. At around nine that night I spotted the restarts in Headlamp.

The fix was one line, adding 127.0.0.0/8 to the allowed sources. I pushed it, deleted one pod stuck in backoff and watched for 14 to 16 minutes with no restarts.

Here is the lesson, now a rule in the repo: after any firewall change, watch the component you changed for longer than its probe period, not just the things it protects. Ten minutes of calico-node is now a written step.

Working with the Agent

I need to be fair here, in both directions.

I asked in plain English: "Security hardening: prevent pods from accessing outside the cluster in my LAN" plus minimal audit logging. The agent proposed the controls, wrote the manifests, ran probe pods before and after, and did the node-by-node rollouts over SSH. It also vendored Calico’s CRD schemas so CI could validate the new objects, because the public catalogue lacks them.

It got a lot right: the lan-guard narrowing, and the Secrets rollout order (read everywhere, then write, then rewrite).

Where it was wrong was verification. It declared the host firewall verified on port scans and a reboot, which are the tests I would have asked for too. I did not catch it either; it took me glancing at Headlamp seven hours later, and I had already set a second agent loose to fix it. The agent laid out the loopback cause and checked the repo for parallel changes before touching anything. I told the other agent to stand down.

Then it wrote the incident into the docs, with the 10-minute watch as a hard rule. In my opinion, an agent that admits fault plainly and writes it down beats one that is defensive.

Wrapping Up

The cluster now has labelled namespaces, default-deny policies, a LAN guard, encrypted Secrets, a minimal audit trail and a host firewall that no longer breaks Calico. It costs almost no memory, but it does cost you a rule: watch what you changed, for longer than you think.

In Part 7 I look at keeping it patched without babysitting it, and the surprise of finding I had flashed the desktop image onto three servers.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It (this post)
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 5): Ingress, Certificates and Getting Home Through CGNAT

Recently I got to the point of publishing apps on the Pi cluster, and I discovered that the ingress story for Kubernetes had changed underneath me. The Kubernetes project announced that Ingress NGINX would be retired in March 2026, with no further releases, bug fixes or security patches after that. In the same window, MicroK8s 1.35 switched its ingress add-on to Traefik. Perfect timing, I thought.

It was perfect timing right up until I found out what the add-on does by default on my kernel, and right up until I tried to reach the thing from outside my home network. I built this cluster in about a day by directing an AI coding agent in my terminal, so this post also covers where my co-pilot earned its keep.

This is Part 5 of the Raspberry Co-PI-lot series. Part 1 built the three-node MicroK8s cluster, Part 2 added Flux and SOPS, Part 3 covered workload identity (which is what lets cert-manager write DNS records without a stored secret) and Part 4 put Entra ID in front of kubectl. The full list is at the bottom of this post.

This post will cover why the add-on’s default exposure does not work on these Pis, how I exposed Traefik instead, how the Gateway API and wildcard certificates fit together, a small private registry (Zot) that uses all of it, and how I get home through CGNAT. Let’s dive in!

In English Please?

Think of the ingress layer as the front desk of a building. Visitors (browsers) arrive at one door, tell the receptionist (Traefik) who they want (the hostname), and get pointed to the right office (a Service). The padlock is the receptionist’s ID badge: a TLS certificate proving the building is who it says it is.

The old way to describe the desk rules was the Ingress object. The newer way is the Gateway API, which splits the job in two: a Gateway (the doors and which certificates they present) and HTTPRoute objects (which hostnames go to which app). I would rather learn the thing the ecosystem is heading towards than the thing that was just retired.

The path of a request on my cluster:

  1. DNS returns the three node IPs for test.lab.example.com.
  2. The client connects to port 443 on one of them.
  3. kube-proxy forwards that to a Traefik pod.
  4. Traefik picks the right wildcard certificate, then routes by hostname to the app.

Why hostPort Does Not Work Here

The MicroK8s add-on runs Traefik as a DaemonSet and, by default, binds ports 80 and 443 on each node with hostPort. On my cluster those pods sat in ContainerCreating with can't initialize iptables table 'nat'.

You may recognise the culprit from Part 1. The Raspberry Pi kernel on these nodes has no legacy ip_tables module, which is why kube-proxy runs in nftables mode. The hostPort feature is implemented by the CNI portmap plugin, and the Calico build shipped with MicroK8s only speaks legacy iptables. This is what I observed on my kernel and MicroK8s version, not something I found documented.

The fix is to skip hostPort entirely. Kubernetes lets you give a Service externalIPs: addresses on which kube-proxy will accept traffic for that Service, if they reach a node. I set them to the three node addresses, so every node answers on 80 and 443 and kube-proxy (already in nftables mode) forwards to any Traefik pod. There is no load balancer and no floating IP; DNS simply returns all three addresses.

Here is the full set of Traefik values from my Flux HelmRelease, with the overrides that matter:

apiVersion: helm.toolkit.fluxcd.io/v2
kind: HelmRelease
metadata:
  name: traefik
  namespace: ingress
spec:
  interval: 1h
  releaseName: traefik
  chart:
    spec:
      chart: traefik
      version: 39.0.8
      sourceRef:
        kind: HelmRepository
        name: traefik
        namespace: flux-system
  install:
    crds: Skip
  upgrade:
    crds: Skip
  values:
    deployment:
      kind: DaemonSet
    ports:
      web:
        port: 8000
        exposedPort: 80
        protocol: TCP
        http:
          redirections:
            entryPoint:
              to: websecure
              scheme: https
              permanent: true
      websecure:
        port: 8443
        exposedPort: 443
        protocol: TCP
        transport:
          respondingTimeouts:
            readTimeout: 600s
    service:
      type: ClusterIP
      externalIPs:
        - 192.168.1.x   # node 1
        - 192.168.1.x   # node 2
        - 192.168.1.x   # node 3
    ingressRoute:
      dashboard:
        enabled: false
    gateway:
      listeners:
        web:
          port: 8000
          protocol: HTTP
          namespacePolicy:
            from: All
        websecure-prod:
          port: 8443
          protocol: HTTPS
          hostname: "*.example.com"
          certificateRefs:
            - name: wildcard-example-com-tls
          namespacePolicy:
            from: All
        websecure-lab:
          port: 8443
          protocol: HTTPS
          hostname: "*.lab.example.com"
          certificateRefs:
            - name: wildcard-lab-example-com-tls
          namespacePolicy:
            from: All
    providers:
      kubernetesIngress:
        enabled: false
      kubernetesGateway:
        enabled: true
      kubernetesIngressNginx:
        enabled: false
      kubernetesCRD:
        enabled: false
    ingressClass:
      enabled: false
    resources:
      requests: { cpu: 25m, memory: 64Mi }
      limits: { memory: 192Mi }

The service block is the externalIPs fix. The dashboard is off because the add-on enables an unauthenticated one by default. The crds: Skip lines are the Part 2 gotcha: the add-on owns the Gateway API CRDs. The 600 second readTimeout is for the registry, below.

Be warned: re-running microk8s enable ingress resets the release to the add-on defaults, hostPort included. It is now a hard rule in the repo’s AGENTS.md, the file of rules the agent reads: never run it again.

Gateway API, Wildcards and Publishing an App

Once Traefik was running, I turned off everything except the Gateway API provider. The Ingress provider, the NGINX-annotation compatibility provider, the Traefik CRD provider and the add-on’s IngressClasses are all disabled. Nothing needed them, and fewer ways to publish a service means fewer surprises.

The Gateway has two HTTPS listeners, *.example.com and *.lab.example.com (for experiments), and port 80 redirects everything to HTTPS.

Publishing an app is three small steps. Here is the route for whoami, my canary: one request to it exercises DNS, kube-proxy, Traefik, the listener and the certificate at once.

apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
  name: whoami
  namespace: whoami
spec:
  parentRefs:
    - name: traefik-gateway
      namespace: ingress
      sectionName: websecure-lab
  hostnames:
    - test.lab.example.com
  rules:
    - backendRefs:
        - name: whoami
          port: 80

The parentRefs attach the route to the lab listener. The last step is a DNS record; I create A records by hand in Azure DNS (the cluster has no write access to those zones, deliberately), one per node IP:

for ip in 192.168.1.x 192.168.1.x 192.168.1.x; do   # your three node IPs
  az network dns record-set a add-record \
    -g rg-<name> -z lab.example.com -n test -a "$ip"
done

Yes, my public DNS contains private addresses. In my opinion that is fine: the same name and certificate then work at home and over a VPN. If your router strips private answers, allow the domain.

Verify the whole chain with one command:

curl -sf https://test.lab.example.com

The certificates come from cert-manager and Let’s Encrypt. Wildcard certificates require the DNS-01 challenge, where you prove control of the domain by publishing a TXT record rather than answering an HTTP request. That suits a cluster nobody can reach from the internet. Part 3 covered how cert-manager authenticates to Azure and why it can only write to a dedicated acme.example.com zone.

On the ingress side that is two Certificate objects, one per listener:

apiVersion: cert-manager.io/v1
kind: Certificate
metadata:
  name: wildcard-example-com
  namespace: ingress
spec:
  secretName: wildcard-example-com-tls
  issuerRef: { name: letsencrypt-prod, kind: ClusterIssuer }
  dnsNames: ["*.example.com"]
---
apiVersion: cert-manager.io/v1
kind: Certificate
metadata:
  name: wildcard-lab-example-com
  namespace: ingress
spec:
  secretName: wildcard-lab-example-com-tls
  issuerRef: { name: letsencrypt-prod, kind: ClusterIssuer }
  dnsNames: ["*.lab.example.com", "lab.example.com"]

The secret names match the certificateRefs on the Gateway listeners, so every app on the lab domain gets a trusted certificate without its own request. I left the apex example.com out of the production certificate because the main domain is served elsewhere.

Note: a wildcard covers one label only. myapp.lab.example.com is covered; foo.bar.lab.example.com is not. And per the Part 3 constraint, a standalone certificate for any name without an _acme-challenge CNAME into the challenge zone will sit in pending forever.

A Private Registry for Next to Nothing

With ingress working, I wanted somewhere to push images I build on my Mac. The MicroK8s registry add-on has no authentication and plain HTTP, so I rejected it. Zot, an OCI-native registry, turned out to be an excellent fit for a Pi: the zot-minimal image sat at about 25 Mi of memory in my cluster.

It is a Flux-managed Helm chart with a 10Gi volume, htpasswd authentication from a SOPS secret and two users: pusher (read and write, for my workstation) and puller (read only, for the cluster). No anonymous access. It sits behind the websecure-lab listener, so registry.lab.example.com already has a trusted certificate and the nodes need no extra configuration.

Two small lessons. First, Traefik’s default 60 second read timeout covers the whole request body, which breaks large layer pushes; that is why I raised readTimeout to 600 seconds in the values above. With that in place, a push of about 45 MB took 18 seconds. Second, a pod without a pull secret got ImagePullBackOff, which is exactly what I wanted to see.

A word from the wise: the registry’s data lives on a single node and is not backed up. Everything in it should be rebuildable from source.

Working With the Agent: Where I Had to Steer

I describe an outcome in plain English, my co-pilot does the typing, and I make the calls. Here are a few moments from this part.

The agent did the research on the ingress-nginx retirement and the MicroK8s add-on change, found that hostPort could not work on this kernel, and moved Traefik to externalIPs. That was the right call. It also wrote the "never re-run microk8s enable ingress" rule into AGENTS.md, so a future session cannot undo the fix by accident. My job was to read what it proposed and decide whether I could live with it.

It was wrong in a small way on the redirect. Its first comment said Traefik answers with a 308; when we tested it, Traefik answered 301. The behaviour was fine, but the comment was a confident claim nobody had checked. The agent is quick, but it is only as trustworthy as the evidence it gathers.

The remote access piece is where I steered most. I was away from home, which is when it hit me that I could not reach any of this, so I asked the agent what my options were. It checked the gateway, tested the candidates and wrote up the trade-offs; I picked the one I could live with.

Getting Home Through CGNAT

My router is a UniFi Gateway Pro Max on Aussie Broadband. The agent checked the WAN address, and it was in 100.64.0.0/10, the range set aside for carrier-grade NAT (RFC 6598). In plain terms, my ISP shares one public address between many customers, so nothing can start a connection to my router. A WireGuard server on the gateway, or a port forward, simply cannot work. That is what I observed.

UniFi Teleport is where this gets workable. Ubiquiti describe it as a VPN built on WireGuard that needs no configuration, and state that it can be used when the gateway is behind NAT. You enable it in the UniFi Network settings, generate an invitation, and accept it in the WiFiman app (mobile or desktop). Their docs note the invitation expires in 24 hours and works on a single device at a time. They also note Teleport requires IPv6 on the gateway’s WAN in some circumstances, which is worth knowing if it misbehaves for you.

I tested it from a phone hotspot, which was a fair stand-in for a hostile network:

  • First attempt failed. The tunnel interfaces came up but had no IPv4 address, and traffic went straight out the hotspot. Reconnecting fixed it.
  • After that it worked. The HTTPS canary returned 200, and kubectl and SSH both worked.
  • It is a full tunnel. All traffic goes via home, and DNS still came from the hotspot, which was fine because my names resolve in public DNS.
  • It dropped twice during testing. In my opinion that is tolerable for a lab.

The fallback, documented but not installed, is a Tailscale subnet router on the host OS of two nodes, advertising only the node IPs.

Nothing on the cluster is exposed to the internet, and the router is never port-forwarded.

Wrapping Up

The cluster now serves HTTPS on trusted wildcard certificates through Traefik and the Gateway API, hosts its own private registry, and I can reach it from anywhere without opening a single inbound port. The unexpected cost was learning that a default which works on most clusters cannot work on mine.

Next up is the part where I lock the whole thing down, and spectacularly break it.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT (this post)
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 4): Entra ID for kubectl, Five Years After Okta

Recently I rebuilt my desk Kubernetes cluster, and as an identity geek the first question was "how will I log in?". Back in 2021 I wrote up how I integrated Kubernetes with Okta for user RBAC on a MicroK8s cluster. It was a pile of --oidc-* flags on the API server, three curl requests to get a token by hand, and kubelogin to tidy it all up. This time I wanted to see what five years of Kubernetes had changed.

Quite a lot, as it turns out. I also found something embarrassing: my 2021 post mentioned that MicroK8s runs with --authorization-mode=AlwaysAllow by default, and I still built a new cluster without checking. Spoiler: it was on. Every pod could have been a cluster admin.

This is Part 4 of the Raspberry Co-PI-lot series, and the earlier parts (rebuilding the cluster, Flux and SOPS, workload identity) are listed at the bottom.

This post will cover fixing that, signing in to kubectl with Microsoft Entra ID, keeping a break-glass way in, and a web dashboard on the same sign-in. My AI coding agent did most of the typing, so I’ll cover how that went too. Let’s dive in!

The scary one first: RBAC was off

Kubernetes decides what you can do in two steps: authentication asks "who are you?" and authorization asks "are you allowed?". Think of a nightclub: the bouncer checks your ID, then someone else decides whether you get into the VIP room. MicroK8s ships with the second person on a long lunch break.

Every pod gets a ServiceAccount token mounted automatically, and under AlwaysAllow that token is effectively cluster-admin. I proved it against my little test app’s identity:

kubectl auth can-i '*' '*' --as=system:serviceaccount:whoami:default

It answered yes. A harmless demo app could have deleted everything in the cluster.

The fix is the MicroK8s rbac add-on, which sets --authorization-mode=RBAC,Node. Be warned: it restarts all three API servers at once. For me that was about a 10 second API blip, with workloads still running and a burst of forbidden log lines while the default roles were created. Afterwards the same check returned no, and a fresh certificate issued by cert-manager (Part 3) still went through.

Note: watch the logs afterwards. A burst of forbidden that stops is normal; one that keeps repeating is a component missing a role.

Structured authentication, not a pile of flags

In 2021, the API server learned about Okta through flags like --oidc-issuer-url and --oidc-username-prefix. Those still exist, but there is now a better way. Kubernetes introduced a file-based AuthenticationConfiguration in 1.29, and the v1.34 release notes list structured authentication configuration as stable. The Kubernetes docs describe it as supporting multiple JWT authenticators, CEL expression validation and dynamic reloading.

In English: instead of squeezing your identity provider into flags, you hand the API server a YAML file saying "trust tokens from this issuer, for this audience, and turn the claims into a username and groups like so". It is easier to review in Git and can describe more than one issuer.

Here is the file from my cluster, with names genericised:

apiVersion: apiserver.config.k8s.io/v1
kind: AuthenticationConfiguration
jwt:
  - issuer:
      url: https://login.microsoftonline.com/<tenant-id>/v2.0
      audiences:
        - <kubectl-app-client-id>
      audienceMatchPolicy: MatchAny
    claimValidationRules:
      - expression: "claims.tid == '<tenant-id>'"
        message: token is not from my tenant
    claimMappings:
      username:
        claim: oid
        prefix: "entra:"
      groups:
        claim: groups
        prefix: "entra:"
      extra:
        - key: example.com/upn
          valueExpression: "has(claims.preferred_username) ? claims.preferred_username : ''"

What it does: only tokens from my tenant, issued to my rpi-k8s-kubectl app registration, are accepted; a CEL rule rejects any token whose tid is not my tenant (belt and braces); the username comes from the oid claim and groups from groups, both prefixed entra: so they can never be confused with a certificate user or ServiceAccount; and the friendly name rides along as extra.

In 2021 I swapped the username claim to preferred_username to make things readable. This time I used the object ID for identity and parked the friendly name in extra, because names change and object IDs don’t.

On MicroK8s the file lives at /var/snap/microk8s/current/args/authentication-config.yaml, and the API server needs one extra flag. I applied it one node at a time, starting with a canary:

sudo install -m 0644 authentication-config.yaml /var/snap/microk8s/current/args/authentication-config.yaml
f=/var/snap/microk8s/current/args/kube-apiserver
grep -q authentication-config $f \
  || echo '--authentication-config=${SNAP_DATA}/args/authentication-config.yaml' | sudo tee -a $f
sudo systemctl restart snap.microk8s.daemon-kubelite
kubectl get nodes

A word from the wise: a syntax error in that file stops the API server on that node starting. That is why it goes one node at a time.

Entra ID, kubelogin and one group

On the Entra side, the setup is modest:

  1. A security group, rpi-k8s-admins, with me in it.
  2. An app registration, rpi-k8s-kubectl, single tenant, as a public client with http://localhost:8000 and http://localhost:18000 redirect URIs.
  3. The groups claim switched on (groupMembershipClaims: SecurityGroup) and admin consent granted.

I was moving to a new Mac, so I wanted nothing tied to the machine: no client secret, no token baked into a kubeconfig. A public client using the browser, with MFA handled by Entra, fits.

On the workstation, kubelogin does the heavy lifting, as in 2021. It is a kubectl credential plugin that opens a browser, caches the tokens and refreshes them. The wiring:

kubectl config set-credentials rpi-k8s-entra --exec-api-version=client.authentication.k8s.io/v1 \
  --exec-interactive-mode=IfAvailable --exec-command=kubectl \
  --exec-arg=oidc-login --exec-arg=get-token \
  --exec-arg=--oidc-issuer-url=https://login.microsoftonline.com/<tenant-id>/v2.0 \
  --exec-arg=--oidc-client-id=<kubectl-app-client-id> \
  --exec-arg=--oidc-extra-scope=profile --exec-arg=--oidc-extra-scope=offline_access
kubectl config set-context rpi-k8s --cluster=rpi-k8s --user=rpi-k8s-entra
kubectl config use-context rpi-k8s
kubectl auth whoami

Unlike 2021 there is no client secret in the kubeconfig. The first kubectl auth whoami opens the browser, I sign in (consenting on behalf of the organisation the first time), and the answer comes back as entra: plus my object ID.

Last piece: tell RBAC what the group is allowed to do. This binding is committed to Git and reconciled by Flux (Part 2):

apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
  name: entra-rpi-k8s-admins
roleRef:
  apiGroup: rbac.authorization.k8s.io
  kind: ClusterRole
  name: cluster-admin
subjects:
  - apiGroup: rbac.authorization.k8s.io
    kind: Group
    name: "entra:<rpi-k8s-admins-group-object-id>"

The group name carries the entra: prefix from the claim mapping. My 2021 binding named one Okta user; this binds a group, so adding or removing an admin is a group change in Entra with no cluster change. Removing someone stops their cached token being useful once it expires.

Note: Entra drops the groups claim for users in more than 200 groups (an overage), per Microsoft’s group claims guidance. Not an issue in my lab, but read that page before doing this in a real tenant.

Break-glass: the certificate I try not to use

What if Entra, or my internet, is the thing that is broken? I kept a way in that depends on neither: the MicroK8s admin client certificate, which authenticates as system:masters and so works even if I fumble every binding.

The downside is that Kubernetes does not support certificate revocation. A leaked admin certificate stays valid until it expires, and short of re-issuing the cluster CA I cannot take it back. So it does not live on my laptop: I fetch it over SSH from a node when needed and merge it in as a rpi-k8s-breakglass context. The last resort is microk8s kubectl on a node.

I accepted that risk knowingly. For a home lab with key-only SSH, it is a sensible trade; in a real environment I would want a shorter-lived emergency credential.

Headlamp, and the wrong-account moment

I also wanted a dashboard. The old Kubernetes Dashboard is now archived, and its README points to Headlamp. Headlamp supports OpenID Connect sign-in and forwards your own token to the API server.

That is the design I wanted: Headlamp has no authority of its own, so what you can do in it is exactly what your Entra identity can do in kubectl. Its ServiceAccount has no bindings at all (the chart’s default cluster-admin binding is off). I reused the same app registration, so the token audience is already trusted and the authentication file needed no change. The extras were a Web redirect URI and a client secret, kept only in SOPS and Key Vault.

Here is the relevant part of the Flux-managed HelmRelease values:

values:
  fullnameOverride: headlamp
  image:
    tag: v0.46.0
  config:
    inCluster: true
    inClusterContextName: rpi-k8s
    staticPlugins:
      enabled: false
    watchPlugins: false
    oidc:
      secret:
        create: false
      externalSecret:
        enabled: true
        name: headlamp-oidc
        hasScopes: true
      usePKCE: true
  env:
    - name: OIDC_CLIENT_ID
      value: <kubectl-app-client-id>
    - name: OIDC_ISSUER_URL
      value: https://login.microsoftonline.com/<tenant-id>/v2.0
    - name: OIDC_SCOPES
      value: openid profile email offline_access
    - name: OIDC_CALLBACK_URL
      value: https://headlamp.lab.example.com/oidc-callback
    - name: OIDC_USE_PKCE
      value: "true"
  clusterRoleBinding:
    create: false

The secret comes from a SOPS-encrypted Secret called headlamp-oidc. No plugins, a restricted Pod Security profile and a default-deny network policy (Part 6) keep it tight, and it idled at about 15 to 16 MiB when I measured, which matters with 3.8 GB per Pi.

Now the fun bit. My first look at Headlamp showed "You don’t have permissions" everywhere. I simply had not signed in, and by design an unauthenticated Headlamp can do nothing.

So I signed in and still had no rights. My work browser profile had signed me in as a guest account from my day job’s tenant, which is not in rpi-k8s-admins, so Kubernetes correctly gave it nothing. I told the agent: "ignore me, when I use the right account it works."

A lovely accidental proof the group binding works. If you juggle tenants, use a dedicated browser profile for lab sign-ins.

Working with the agent

Everything above was built by me directing an AI coding agent in my terminal. How it went:

  • The finding. The agent spotted AlwaysAllow during its research pass (about 01:00) and proved it with the can-i check. I asked for RBAC on, then Entra sign-in, with the constraint that nothing be tied to my old laptop.
  • What it did well. It canaried the authentication file on node 1 and confirmed the API answered before touching the others, and the break-glass context stayed in my kubeconfig throughout. It also checked results (can-i before and after) rather than just saying "done".
  • Where I was needed. The agent cannot complete a browser sign-in with MFA, so the first kubelogin run and the consent were mine. Reusing the one app registration for Headlamp was the agent’s recommendation, with the trade-off spelled out (no node change, but a client secret on a public-client app); I went with it. The break-glass risk was my call too.
  • A wrong-account moment, mine. The agent could not know which browser profile I would use.
  • Away from home. From somewhere without Wi-Fi I pasted a screenshot and asked it to stop a running job; it cancelled the (read-only) one.

Headlamp also paid for itself quickly: it surfaced a flapping readiness probe on the local-path provisioner, fixed with a longer timeout and more memory headroom. And in Part 6 it is how I noticed a Calico crashloop.

Wrapping Up

Five years on, the shape is the same (token from the identity provider, kubelogin, RBAC decides), but the API server config is a reviewable file, access is a group instead of a named user, and I now check RBAC is actually on. Next in Part 5: ingress, certificates and getting home through CGNAT.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta (this post)
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 3): Workload Identity Without AKS

Recently I decided my Raspberry Pi cluster should talk to Azure without a single secret living inside it. No client secrets, nothing for a future me to rotate or leak.

This is Part 3 of a series. In Part 1 I rebuilt the cluster, and in Part 2 I put it under GitOps with Flux and SOPS. All the titles are listed at the end.

On AKS that is close to a checkbox. On a desk full of Pis it is mostly plumbing, but small enough to understand end to end. Back in 2020 I got Azure Arc running on a Pi cluster; this time I wanted Azure to trust the cluster instead.

This post will cover how workload identity federation works, how I self-hosted the OIDC issuer on a public blob container, how cert-manager uses it for DNS-01 certificates, and how a systemd timer uses it for nightly dqlite backups. Let’s dive in!

In English Please?

Think of a pub that accepts your work ID as proof you are an employee, so you get the staff discount without the pub ever issuing you a card. The pub does not hold a copy of your credentials. It just trusts your employer’s stamp, and checks the stamp is real.

Kubernetes already issues every service account a signed token (a JWT). With workload identity federation, Microsoft Entra ID can be told to trust tokens from a particular issuer for a particular subject. The cluster presents a token, Entra checks the signature against the issuer’s public keys, and hands back a normal Entra access token for a managed identity. The only thing Entra needs is a public URL where it can read the issuer’s discovery document and public keys.

AKS hosts that URL for you; I host it myself. The Entra docs for federated credentials cover the Kubernetes scenario, and the Azure Workload Identity docs for self-managed clusters describe the two documents I publish below.

Self-Hosting the OIDC Issuer

Entra needs two documents: a discovery document at .well-known/openid-configuration, and a JWKS (JSON Web Key Set) at openid/v1/jwks holding the public signing keys. Neither is secret. I put them in a blob container with anonymous read on a storage account, so the issuer URL is https://st<name>oidc.blob.core.windows.net/oidc.

A small script generates both, pulling the key set from the API server itself:

#!/usr/bin/env bash
# Generate the public OIDC discovery documents for the cluster's service-account issuer.
# Usage: scripts/oidc/generate.sh https://<account>.blob.core.windows.net/oidc [outdir]
# Upload the outputs to the container with blob names:
#   .well-known/openid-configuration
#   openid/v1/jwks
set -euo pipefail
issuer="${1:?issuer URL required, e.g. https://<account>.blob.core.windows.net/oidc}"
issuer="${issuer%/}"
out="${2:-./oidc-out}"
mkdir -p "$out/.well-known" "$out/openid/v1"

kubectl --context rpi-k8s get --raw /openid/v1/jwks > "$out/openid/v1/jwks"

cat > "$out/.well-known/openid-configuration" <<EOF
{
  "issuer": "${issuer}",
  "jwks_uri": "${issuer}/openid/v1/jwks",
  "response_types_supported": ["id_token"],
  "subject_types_supported": ["public"],
  "id_token_signing_alg_values_supported": ["RS256"]
}
EOF
echo "Wrote $out/.well-known/openid-configuration and $out/openid/v1/jwks"

I uploaded both files with those exact blob names and checked in a private browser window that both URLs returned JSON.

Next, each API server has to stamp its tokens with that issuer. In the MicroK8s args file /var/snap/microk8s/current/args/kube-apiserver I added these flags:

--service-account-issuer=https://st<name>oidc.blob.core.windows.net/oidc
--service-account-issuer=https://kubernetes.default.svc
--service-account-jwks-uri=https://st<name>oidc.blob.core.windows.net/oidc/openid/v1/jwks

The kube-apiserver reference says that when the issuer flag is given more than once, the first is used to generate tokens. That is why the blob URL goes first and the old in-cluster issuer stays second, so tokens already issued stay valid. The JWKS URI flag overrides where the discovery document points for keys. The API server’s own address is private, so Entra gets pointed at the blob instead.

I rolled this out one node at a time and restarted snap.microk8s.daemon-kubelite on each, because a typo in that file stops the API server starting on that node.

Note: all three nodes must share the same service account signing key, otherwise one JWKS cannot cover them all. On MicroK8s that is /var/snap/microk8s/current/certs/serviceaccount.key. Check it with sha256sum on each node before trusting tokens from it. If the key ever changes, rerun the script and re-upload the JWKS, or every token exchange will fail.

The last Azure piece is a user-assigned managed identity per consumer, each with a federated credential: issuer set to the blob URL exactly (no trailing slash), subject system:serviceaccount:<namespace>:<serviceaccount>, audience api://AzureADTokenExchange.

Using it without the webhook

AKS adds a mutating webhook that injects the token and environment variables into labelled pods. I did not install it. A projected token volume and four environment variables do the same job. These are the cert-manager Helm values from my Flux HelmRelease:

values:
  crds:
    enabled: true
  # DNS-01 self-checks must use public resolvers (CNAME-delegated challenges in acme.example.com).
  dns01RecursiveNameservers: "1.1.1.1:53,8.8.8.8:53"
  dns01RecursiveNameserversOnly: true
  serviceAccount:
    name: cert-manager   # must match the federated credential subject
  extraEnv:
    - name: AZURE_CLIENT_ID
      value: <cert-manager-managed-identity-client-id>
    - name: AZURE_TENANT_ID
      value: <tenant-id>
    - name: AZURE_FEDERATED_TOKEN_FILE
      value: /var/run/secrets/azure/tokens/azure-identity-token
    - name: AZURE_AUTHORITY_HOST
      value: https://login.microsoftonline.com/
  volumes:
    - name: azure-identity-token
      projected:
        sources:
          - serviceAccountToken:
              audience: api://AzureADTokenExchange
              expirationSeconds: 3600
              path: azure-identity-token
  volumeMounts:
    - name: azure-identity-token
      mountPath: /var/run/secrets/azure/tokens
      readOnly: true

The cert-manager Azure DNS docs show the same variables and projected volume as the webhook’s output, so I wrote them by hand. The Azure SDK reads the token file and swaps it with Entra. The service account name must stay cert-manager, because that is what the federated credential trusts.

DNS-01 Without Giving Away My Domain

I wanted wildcard certificates from Let’s Encrypt, which means DNS-01 challenges. That needs write access to DNS, and I was not keen on giving a Pi write access to a domain that also holds my mail records.

The fix is delegation. Let’s Encrypt follows CNAMEs when it looks up the challenge record, so I created a child zone acme.example.com that holds nothing but challenge records, and gave the cert-manager identity DNS Zone Contributor on that zone only. Then I created one static CNAME per real zone, once, by hand:

  • _acme-challenge.example.com points to example-com.acme.example.com
  • _acme-challenge.lab.example.com points to lab-example-com.acme.example.com

cert-manager’s delegated domains support does the rest with cnameStrategy: Follow:

apiVersion: cert-manager.io/v1
kind: ClusterIssuer
metadata:
  name: letsencrypt-prod
spec:
  acme:
    server: https://acme-v02.api.letsencrypt.org/directory
    email: <your-email>
    privateKeySecretRef:
      name: letsencrypt-prod-account
    solvers:
      - dns01:
          cnameStrategy: Follow
          azureDNS:
            subscriptionID: <subscription-id>
            resourceGroupName: rg-dns   # resource group of the acme.example.com zone
            hostedZoneName: acme.example.com
            environment: AzurePublicCloud
            managedIdentity:
              clientID: <cert-manager-managed-identity-client-id>

The two wildcard certificates are then ordinary cert-manager resources:

apiVersion: cert-manager.io/v1
kind: Certificate
metadata:
  name: wildcard-example-com
  namespace: ingress
spec:
  secretName: wildcard-example-com-tls
  issuerRef: { name: letsencrypt-prod, kind: ClusterIssuer }
  dnsNames: ["*.example.com"]   # apex deliberately excluded
---
apiVersion: cert-manager.io/v1
kind: Certificate
metadata:
  name: wildcard-lab-example-com
  namespace: ingress
spec:
  secretName: wildcard-lab-example-com-tls
  issuerRef: { name: letsencrypt-prod, kind: ClusterIssuer }
  dnsNames: ["*.lab.example.com", "lab.example.com"]

Be warned: resourceGroupName is the resource group of the DNS zone, not of the managed identity. We got that wrong the first time (the git history has a "fix issuer RG" commit to prove it).

A word from the wise: only names with an _acme-challenge CNAME into the challenge zone can get a certificate. When I tried a certificate for a single name with no CNAME, the challenge stayed pending forever. The wildcard certificates cover everything under them, so in practice I use those. For anything else, create the CNAME first, and remember a CNAME cannot sit alongside a TXT record at the same name. The Part 5 post shows how these certificates get used for ingress.

The Backup Timer: Workload Identity on the Host

The second consumer is not a pod. Every night each node backs up the MicroK8s datastore (dqlite, which holds every Kubernetes object, Secrets included) to blob storage. A systemd timer starts a script that mints its own short-lived service account token and trades it with Entra.

The service account is deliberately boring. No pods run in that namespace and no token is mounted:

apiVersion: v1
kind: Namespace
metadata:
  name: backup
  labels:
    pod-security.kubernetes.io/enforce: restricted
---
apiVersion: v1
kind: ServiceAccount
metadata:
  name: dqlite-backup
  namespace: backup
automountServiceAccountToken: false

The script (installed at /usr/local/sbin/) uses kubectl create token to get a ten-minute token with the right audience, posts it to the Entra token endpoint as a client assertion, and uploads the archive with the resulting bearer token:

#!/usr/bin/env bash
# /usr/local/sbin/microk8s-dqlite-backup
# Back up the MicroK8s dqlite datastore and upload it to Azure Blob Storage.
set -euo pipefail

TENANT_ID=<tenant-id>
CLIENT_ID=<backup-managed-identity-client-id>
ACCOUNT=st<name>backup
CONTAINER=dqlite
LOCAL_DIR=/var/backups/microk8s
KEEP_LOCAL=3
MICROK8S=/snap/bin/microk8s

host=$(hostname)
ts=$(date -u +%Y%m%dT%H%M%SZ)
name="${host}-${ts}"

install -d -m 700 "$LOCAL_DIR"
work=$(mktemp -d "$LOCAL_DIR/.work.XXXXXX")
trap 'rm -rf "$work"' EXIT

echo "backing up dqlite to $LOCAL_DIR/$name.tar.gz"
( cd "$work" && "$MICROK8S" dbctl backup -o "$name" >/dev/null )
archive=$(find "$work" -maxdepth 1 -name "$name*.tar.gz" -print -quit)
[ -n "$archive" ] || { echo "dbctl backup produced no archive" >&2; exit 1; }
tar -tzf "$archive" >/dev/null   # integrity check
mv "$archive" "$LOCAL_DIR/$name.tar.gz"
archive="$LOCAL_DIR/$name.tar.gz"
size=$(stat -c %s "$archive")
sha=$(sha256sum "$archive" | cut -d' ' -f1)

sa_token=$("$MICROK8S" kubectl create token dqlite-backup -n backup \
  --audience api://AzureADTokenExchange --duration 10m)

access_token=$(curl -fsS -X POST "https://login.microsoftonline.com/${TENANT_ID}/oauth2/v2.0/token" \
  --data-urlencode "client_id=${CLIENT_ID}" \
  --data-urlencode "scope=https://storage.azure.com/.default" \
  --data-urlencode "grant_type=client_credentials" \
  --data-urlencode "client_assertion_type=urn:ietf:params:oauth:client-assertion-type:jwt-bearer" \
  --data-urlencode "client_assertion=${sa_token}" \
  | python3 -c 'import json,sys; print(json.load(sys.stdin)["access_token"])')

url="https://${ACCOUNT}.blob.core.windows.net/${CONTAINER}/dqlite/${host}/${name}.tar.gz"
curl -fsS -X PUT "$url" -T "$archive" \
  -H "Authorization: Bearer ${access_token}" \
  -H "x-ms-version: 2023-11-03" \
  -H "x-ms-blob-type: BlockBlob" \
  -H "x-ms-blob-content-type: application/gzip" \
  -H "x-ms-meta-sha256: ${sha}" \
  -o /dev/null
echo "uploaded ${size} bytes sha256=${sha} to ${url}"

# Keep the newest KEEP_LOCAL archives locally.
# shellcheck disable=SC2012
ls -1t "$LOCAL_DIR"/*.tar.gz 2>/dev/null | tail -n +$((KEEP_LOCAL + 1)) | xargs -r rm -f

Each run produces an archive (about 4.3 MB here), checks it is a valid tarball, records a SHA-256 as blob metadata and keeps the newest three copies locally. The service and timer are short:

# /etc/systemd/system/microk8s-dqlite-backup.service
[Unit]
Description=Back up MicroK8s dqlite datastore to Azure Blob
Wants=network-online.target
After=network-online.target snap.microk8s.daemon-k8s-dqlite.service

[Service]
Type=oneshot
ExecStart=/usr/local/sbin/microk8s-dqlite-backup
Nice=10
IOSchedulingClass=idle
# /etc/systemd/system/microk8s-dqlite-backup.timer
[Unit]
Description=Daily MicroK8s dqlite backup

[Timer]
OnCalendar=*-*-* 01:00:00
RandomizedDelaySec=45min
FixedRandomDelay=true
Persistent=true

[Install]
WantedBy=timers.target

The systemd timer docs explain FixedRandomDelay: the random delay is derived deterministically, so each node gets its own stable offset between 01:00 and 01:45. The nodes never back up at once, and the offsets stay clear of the Sunday snap refresh windows. Persistent=true catches up if a node was off.

The storage account has shared-key access disabled and anonymous access off, so Entra bearer tokens are the only way in. A lifecycle rule deletes blobs after 30 days. Downloading one archive to a workstation and comparing its hash against the blob metadata showed they matched.

Note: I have not yet rehearsed a restore on this cluster. A backup you have never restored is a hope, not a backup, so a throwaway single-node rebuild is on my list.

Least privilege

Each identity can do exactly one thing:

Identity Federated subject Role Scope
cert-manager managed identity system:serviceaccount:cert-manager:cert-manager DNS Zone Contributor the acme.example.com zone only
Backup managed identity system:serviceaccount:backup:dqlite-backup Storage Blob Data Contributor the dqlite container only

A stolen cert-manager token could write TXT records in a zone that holds nothing else, and only for an hour (ten minutes for the backup token). The nicest property is that there is nothing to rotate: the signing key lives on the nodes, the public half lives in a blob, and Entra does the trusting.

Working With the Agent

As with the rest of this series, my co-pilot did most of the typing. This part took roughly an hour and a quarter on the evening of 15 November, from about 22:30 to 23:46.

What I asked for was simple: Azure access with no stored secrets. The agent proposed the self-hosted issuer, wrote the generator script, a portal runbook for the Azure steps (the commit is called "workload identity portal runbook") and rolled the API server flags out one node at a time, in line with the hard rules in its AGENTS.md file. It also did the less glamorous work: proving the end-to-end path by getting both wildcard certificates issued, and verifying the backup by downloading it and comparing hashes rather than just trusting a 200.

It was not flawless. The resource group slip above was a mistake (the agent’s, caught when the first issuer would not work), and the stuck single-name certificate was a constraint we discovered by hitting it, then documented. Later, as part of hardening, the OIDC storage account had its shared-key access turned off. When it came to money, it asked first: it checked whether I wanted to switch a storage account to locally redundant storage, and I said geo-redundant was fine. That was my call to make, not its.

Wrapping Up

With a public blob, two flags on the API server and a projected token, a self-managed cluster can do the same workload identity trick as AKS: no secrets, short-lived tokens and narrow roles. Next up is Part 4, where I tackle the scary finding that every token on this cluster was effectively cluster-admin, and wire Entra ID into kubectl, five years after my Okta post.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS (this post)
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 2): GitOps and Secrets with Flux and SOPS

Recently I rebuilt my desk cluster, and by the time I had cert-manager and Traefik running, I had also run a lot of kubectl apply and helm install commands. Most of them were typed by my AI coding agent, to be fair, but the effect was the same. I could already feel the drift creeping in: what was actually running, and what would I rebuild from if an SD card died?

The answer, as always, is GitOps. This time I wanted it to cover secrets too, and I wanted guardrails, because the thing doing most of the typing is a very fast, very confident AI.

This is Part 2 of a series. In Part 1 (Rebuilding My Desk Kubernetes Cluster, Five Years On) I rebuilt the cluster from scratch. If you want the really long back story, my 2020 post on Azure Arc on an RPi cluster is where this all started.

This post will cover bootstrapping Flux on a Pi cluster, adopting Helm releases that were installed by hand, keeping Flux inside a tiny memory budget, SOPS with two recipients, and the lint pipeline and rules I use to keep the agent in its lane. Let’s dive in!

In English Please?

GitOps means Git is the source of truth for the cluster. You describe what you want in a repository, and a controller inside the cluster continually pulls that repository and makes reality match it.

Think of it like a thermostat. You set the temperature once (the commit), and Flux keeps nudging the room back to that number, even if someone opens a window (a hand-made kubectl edit).

Flux is the controller I picked. SOPS is the other half: a tool that encrypts the values inside a YAML file but leaves the structure readable, so I can commit secrets to Git and still review diffs.

Bootstrapping Flux and the repo layout

The bootstrap is one command. Flux installs its controllers, pushes its own manifests to the repo, and then manages itself from there. I only installed three controllers (source, kustomize and helm) because the notification and image automation controllers cost memory I do not have.

kubectl create ns flux-system
kubectl -n flux-system create secret generic sops-age \
  --from-file=age.agekey=$HOME/.config/sops/age/rpi-k8s.agekey

flux bootstrap github \
  --owner=<github-user> --repository=rpi-k8s --personal --private --branch=main \
  --path=clusters/rpi-k8s \
  --components=source-controller,kustomize-controller,helm-controller

The sops-age secret has to exist before anything encrypted reconciles. It is the one object I create by hand.

Flux’s bootstrap docs describe the deploy key option: the cluster gets an SSH key, and the matching GitHub deploy key is read-only by default. That is exactly what I want. The cluster can pull from the repo but can never push to it, so a compromised Pi cannot rewrite my history. The sync object that bootstrap generated uses an ssh://git@github.com/... URL, which is what I observed on my cluster.

The repository layout is deliberately boring:

clusters/rpi-k8s/
  flux-system/            Flux itself (generated, plus my memory patches)
  infrastructure.yaml     Kustomizations: infra-controllers, then infra-configs
  apps.yaml               Kustomization: apps (after infra-configs)
infrastructure/
  controllers/            HelmRepositories + HelmReleases (cert-manager, traefik, kured)
  configs/                ClusterIssuers, Certificates, RBAC, network policy
apps/                     workloads: whoami (canary), registry, dashboard, LLM gateway

The dependency chain is what makes this safe. Each stage waits for the previous one to be healthy, so CRDs and controllers exist before anything tries to use them:

apiVersion: kustomize.toolkit.fluxcd.io/v1
kind: Kustomization
metadata:
  name: infra-configs
  namespace: flux-system
spec:
  dependsOn:
    - name: infra-controllers
  interval: 1h
  retryInterval: 2m
  timeout: 10m
  path: ./infrastructure/configs
  prune: true
  wait: true
  sourceRef:
    kind: GitRepository
    name: flux-system
  decryption:
    provider: sops
    secretRef:
      name: sops-age

dependsOn plus wait: true gives me the ordering, and prune: true means deleting a file from Git deletes the object. Note that only infra-configs and apps have the decryption block. infra-controllers does not, so secrets must never live under infrastructure/controllers/.

Adopting releases I installed by hand

Here is the awkward bit. cert-manager was installed with helm install, and Traefik arrived via the MicroK8s ingress add-on. Neither was in Git. I needed Flux to take them over without restarting anything.

The trick is that a HelmRelease can reuse the existing release name and namespace. Flux then upgrades the existing release instead of creating a new one. But "should be fine" is not evidence, so before committing I diffed what Helm would render against what was actually installed:

helm template cert-manager jetstack/cert-manager --version <pinned> \
  --namespace cert-manager -f values.yaml > /tmp/wanted.yaml
helm get manifest cert-manager -n cert-manager > /tmp/live.yaml
diff /tmp/wanted.yaml /tmp/live.yaml

The only differences were Helm hook resources and whitespace, which is what I expected. Once that was true, adoption was a no-op. I did the same for Traefik.

Be warned: Traefik still found a way to bite. The first upgrade failed, because the Traefik chart bundles older Gateway API CRDs than the ones the MicroK8s add-on installed. A ValidatingAdmissionPolicy called safe-upgrades.gateway.networking.k8s.io (part of the Gateway API project’s CRD packaging, as I saw it on the cluster) refused the downgrade.

The fix is to tell Helm to leave CRDs alone:

spec:
  # Gateway API CRDs (v1.5+) come from the MicroK8s add-on. The chart bundles older ones, and the
  # Gateway API `safe-upgrades` ValidatingAdmissionPolicy rejects downgrades, so never touch CRDs here.
  install:
    crds: Skip
  upgrade:
    crds: Skip

Squeezing Flux into a Pi

Memory is tight on a 3.8 GB Pi. Flux’s stock manifests give each controller a 1 Gi memory limit. I measured the controllers idling at 36 to 52 Mi, so a 1 Gi ceiling is a lot of rope.

I capped them with kustomize patches in clusters/rpi-k8s/flux-system/kustomization.yaml:

apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- gotk-components.yaml
- gotk-sync.yaml
patches:
- target:
    kind: Deployment
    labelSelector: app.kubernetes.io/part-of=flux
  patch: |
    - op: replace
      path: /spec/template/spec/containers/0/resources
      value:
        requests: { cpu: 25m, memory: 48Mi }
        limits: { memory: 256Mi }
- target:
    kind: Deployment
    name: helm-controller
  patch: |
    - op: replace
      path: /spec/template/spec/containers/0/resources/limits/memory
      value: 384Mi

The patches sit in kustomization.yaml rather than the generated gotk-components.yaml, so they survive re-running flux bootstrap. The helm-controller gets 384 Mi because it renders charts.

SOPS with two recipients

This is the part I am happiest with. Flux needs to decrypt secrets unattended, so it needs a key that lives in the cluster. I, on the other hand, do not want a private key file sitting on every laptop I own.

SOPS can encrypt one file to several recipients, and any one of them can decrypt. So I use two: an age key for Flux, and an Azure Key Vault key for people. My .sops.yaml looks like this (public key material only, names genericised):

creation_rules:
  - path_regex: (infrastructure|apps)/.*\.sops\.ya?ml$
    encrypted_regex: ^(data|stringData)$
    age: age1<public-key>
    azure_keyvault: https://kv-<name>.vault.azure.net/keys/sops/<key-version>

The encrypted_regex encrypts only data and stringData, so names and metadata stay readable in pull requests (Flux’s SOPS guide notes that encrypting a Secret’s other metadata is not supported by kustomize-controller anyway). The Key Vault key is non-exportable, so decrypting needs a signed-in Azure identity: az login and MFA.

Creating a secret is then three commands:

kubectl create secret generic my-secret -n my-ns --from-literal=key=value \
  --dry-run=client -o yaml > apps/my-app/my-secret.sops.yaml
sops -e -i apps/my-app/my-secret.sops.yaml
git add apps/my-app/my-secret.sops.yaml

To prove Key Vault worked on its own, I pointed the age key at a path that does not exist and decrypted anyway:

SOPS_AGE_KEY_FILE=/nonexistent sops -d apps/my-app/my-secret.sops.yaml

It decrypted, which means the Key Vault recipient was doing the work. Earlier, an end-to-end test with a throwaway secret showed it appear decrypted in the cluster, then get pruned when I removed it from Git.

A word from the wise: back up the age private key (mine is in Key Vault and a password manager). Lose every recipient key and those files are unreadable forever.

Working with the agent

I did not hand-write most of this. I asked my terminal coding agent to move everything into Flux, and it restructured the repo into infrastructure/controllers, infrastructure/configs and apps, wrote the HelmReleases, and bootstrapped Flux. In my opinion the diff-before-adopt step is the one worth copying: prove adoption is a no-op before letting Flux touch a running cert-manager, instead of hoping.

It also measured the Flux controllers rather than guessing, and wrote the memory patches. When the Traefik upgrade failed, the admission policy denial pointed at the CRD clash, and the fix was a two-line values change.

Where I had to make calls was the human side of the secrets. The agent started with an age key, which got Flux working end to end. The next morning I was about to move to a new Mac and wanted nothing tied to the laptop, so we added the Key Vault key as a second recipient. The guardrails live in a file called AGENTS.md at the root of the repo, which the agent reads before it works. A few of its hard rules that matter most for this post:

  • Rule 1: Never commit plaintext secrets.
  • Rule 2: Git is the source of truth. Do not kubectl apply/edit/patch or helm upgrade anything Flux manages.
  • Rule 8: Verify after every change. Do not claim success without evidence.
  • Rule 11: Never print decrypted secret values into logs, PR text, issues or docs.

Rules are only words, though. CI is what actually holds the agent (and me, at midnight) to them.

The lint pipeline

Every push runs a GitHub Actions workflow with separate jobs (markdown, yamllint, Kubernetes manifests, Helm renders, secrets, shellcheck and actionlint), so a failure names the problem. The same checks run locally with scripts/ci/lint-all.sh, so the agent runs them before it pushes.

The Kubernetes job builds every path Flux reconciles with kustomize build, then validates the output with kubeconform in strict mode. The key detail is that the Kubernetes version comes from a single file, the MicroK8s track pin, so validation always matches what the cluster runs:

ci_kubeconform() {
  kubeconform \
    -strict \
    -skip CustomResourceDefinition \
    -summary \
    -kubernetes-version "$KUBERNETES_VERSION" \
    -schema-location default \
    -schema-location 'https://raw.githubusercontent.com/datreeio/CRDs-catalog/main/{{.Group}}/{{.ResourceKind}}_{{.ResourceAPIVersion}}.json' \
    -schema-location "$(git rev-parse --show-toplevel)/scripts/ci/schemas/{{.Group}}/{{.ResourceKind}}_{{.ResourceAPIVersion}}.json" \
    "$@"
}

I deliberately did not use -ignore-missing-schemas. A typo in a kind should fail the build, not be skipped. The catch is that the public datree CRDs catalogue did not have schemas for Calico’s policy resources, so the checks could not validate them. The agent vendored those schemas into scripts/ci/schemas/ from the cluster’s own CRDs, and the third -schema-location picks them up.

A second job renders every HelmRelease with helm template and validates the output, catching bad values and chart versions that do not exist.

The secrets job is the one that earns its keep:

  secrets:
    name: Secrets
    runs-on: ubuntu-24.04
    steps:
      - uses: actions/checkout@<pinned-sha>
        with:
          fetch-depth: 0 # gitleaks scans the full history
          persist-credentials: false
      - uses: actions/setup-python@<pinned-sha>
        with:
          python-version: "3.12"
      - run: pip install "pyyaml==${PYYAML_VERSION}"
      # *.sops.yaml are encrypted; no Secret manifest exists outside them.
      - run: scripts/ci/check-sops.sh
      - name: Install gitleaks
        run: |
          # download pinned release, verify its SHA-256, extract
      - run: gitleaks git --redact --no-banner --verbose .

check-sops.sh fails the build if a *.sops.yaml file has no sops: block, if any value is not an ENC[AES256_GCM, string, or if a Secret manifest exists outside a .sops.yaml file. Then gitleaks scans the whole history for credential-shaped strings. Plaintext has to beat both.

My first real CI run went green across all seven jobs.

What I’d watch out for

  • Hand edits vanish. That is the point, but it surprises you the first time. flux suspend kustomization apps while debugging by hand, then flux resume.
  • Pods do not pick up changed secrets automatically if they read them as environment variables. Restart the workload after Flux applies the change.
  • Order your recipients before your files. If you rotate the age key, apply the new in-cluster sops-age secret before Flux reconciles files encrypted to it, or infra-configs and apps will fail to decrypt.

Wrapping Up

The cluster now rebuilds from a Git repo, secrets live in that repo safely, and a CI pipeline plus a short rulebook keep my agent (and me) from the classic mistakes. The agent is fast, so the guardrails matter more, not less. In Part 3 I will give the cluster access to Azure without storing a single secret in it.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On
  2. GitOps and Secrets with Flux and SOPS (this post)
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Raspberry Co-PI-lot (Part 1): Rebuilding My Desk Kubernetes Cluster, Five Years On

Recently I bricked the MicroK8s cluster that had been humming away on my desk. It had stopped being a cluster and become a very expensive paperweight.

Five years ago I wrote about enabling Azure Arc on a Raspberry Pi Kubernetes cluster, and a few months later about integrating Kubernetes with Okta for user RBAC. This is what that cluster looked like back then:

My Raspberry Pi cluster on the desk, back in 2020

Two Pis, a pile of cables, and (as I discovered at the time) an Arc agent that couldn’t run on it because the images were amd64 only. Charming, but not exactly a platform.

So I decided to rebuild it properly. The twist is that I didn’t type most of it. I sat in a terminal on my Mac, described what I wanted in plain English, and let an AI coding agent do the typing. I made the calls; it ran the commands. The whole series (nine parts, fortnightly) comes out of that one build, which was 63 commits over about 24 hours, sleep included.

This post will cover why I picked MicroK8s, the node prep, the kernel gotcha that nearly derailed the day, forming a three-node HA cluster, and what working with the agent was actually like. Let’s dive in!

What I’m Building (and Why MicroK8s)

The hardware is three Raspberry Pi 4 Model B boards (4 GB RAM, 64 GB SD cards) running Raspberry Pi OS based on Debian 13 ("trixie"). In this series I’ll use 192.168.1.x for the node addresses.

For the Kubernetes distribution I went with MicroK8s. Think of it as a full Kubernetes that arrives as a single snap package: one install command per node, and the control plane, kubelet and container runtime come along in the box. When you have three or more nodes it turns on high availability automatically, using dqlite as the clustered datastore instead of etcd. Add-ons such as DNS and ingress are one microk8s enable away.

The honest trade-off: k3s is the other obvious choice for a Pi, and I haven’t benchmarked the two against each other here. I picked MicroK8s because the HA story and the add-ons are built in and I wanted to get to the interesting parts quickly. In my opinion that is the right call for a lab, but Part 7 covers what it cost me on the patching side.

Every node is both control plane and worker. With 3.8 GB of usable RAM per Pi, memory is the scarce resource for this entire series, so every component I add will come with a real number attached.

Prepping the Nodes

Before MicroK8s will run happily on a Pi, two things need sorting. Neither is hard, but both bite if you skip them.

First, the Raspberry Pi kernel ships with the memory cgroup controller switched off, and Kubernetes needs it. Canonical’s Raspberry Pi guide says to append two boot parameters to cmdline.txt. This command backs the file up and adds them only if they aren’t already there:

sudo cp -n /boot/firmware/cmdline.txt /boot/firmware/cmdline.txt.bak
grep -q cgroup_memory=1 /boot/firmware/cmdline.txt \
  || sudo sed -i '1 s/$/ cgroup_enable=memory cgroup_memory=1/' /boot/firmware/cmdline.txt

cmdline.txt must stay a single line, which is why the sed appends to line 1 instead of adding a new one.

Second, Debian doesn’t ship snapd, and MicroK8s is a snap. So I installed it and rebooted, then checked that the memory controller appeared:

sudo apt-get update
sudo apt-get install -y snapd
sudo systemctl reboot
# after boot, `memory` must be listed:
cat /sys/fs/cgroup/cgroup.controllers
# cpuset cpu io memory pids

Note: If memory is missing from that list, don’t carry on. Nothing fails loudly; the node just never becomes Ready and you waste an evening reading kubelet logs. Check it on every node before moving on.

Installing MicroK8s (and the Channel I Didn’t Use)

The Canonical guide installs --channel=1.30. I use the 1.36 track instead, and I’ll tell you why in the agent section below. A snap channel is a track (the Kubernetes minor version) plus a risk level, and per the MicroK8s docs, following a specific track means you only get patch releases and never a surprise new minor. That is exactly what I want on a cluster I don’t intend to babysit:

sudo snap install microk8s --classic --channel=1.36/stable
sudo usermod -aG microk8s admin   # takes effect on next login

The first small gotcha: on Debian, /snap/bin isn’t in sudo’s secure_path, so sudo microk8s status returns "command not found". Either use sudo /snap/bin/microk8s ... or, once you’re in the microk8s group, drop the sudo entirely.

The Kernel Gotcha: 65 Crashloops

Then the big one. With 1.36 installed, microk8s status said "not running", and the kubelite service had restarted 65 times within minutes. The journal said:

modprobe: FATAL: Module ip_tables not found in directory /lib/modules/6.18.50+rpt-rpi-v8
Error: iptables is not available on this host : error listing chain "POSTROUTING" in table "nat"
F... daemon.go:47] Proxy exited iptables is not available on this host

In English please: kube-proxy is the component that turns a Kubernetes Service address into "go to one of these pods". By default it does that by writing iptables rules. The Raspberry Pi 6.18 kernel has the newer nf_tables but no legacy ip_tables module, and the iptables binary bundled in the MicroK8s snap is the legacy flavour. So kube-proxy fails on start, and because it runs inside kubelite, it drags the whole control plane down with it.

The fix is to tell kube-proxy to use its nftables mode (which needs kernel 5.13 or later) by adding one flag:

f=/var/snap/microk8s/current/args/kube-proxy
grep -q proxy-mode $f || echo "--proxy-mode=nftables" | sudo tee -a $f
sudo systemctl restart snap.microk8s.daemon-kubelite

That is the entire fix. The agent applied it to node 1 as a canary, confirmed kubelite stayed up, then rolled it to the other two. The setting survives joins and reboots, but I re-check it after every MicroK8s minor upgrade (more on that in Part 7).

Be warned: this one flag has ripple effects. The same missing ip_tables module is why the ingress add-on’s hostPort defaults can’t work on this kernel, and I’ll get to that in Part 5.

Forming the HA Cluster

With all three nodes healthy individually, forming the cluster is pretty straightforward. On node 1 I generate a single-use join token, then run the printed command on node 2. Repeat with a fresh token for node 3:

sudo /snap/bin/microk8s add-node --format short
# -> microk8s join 192.168.1.x:25000/<token>/<cert-hash>
sudo /snap/bin/microk8s join 192.168.1.x:25000/<token>/<cert-hash>

With the third node in, MicroK8s turned on HA by itself:

$ microk8s status
microk8s is running
high-availability: yes
  datastore master nodes: 192.168.1.x:19001 192.168.1.x:19001 192.168.1.x:19001

The agent also merged the new cluster into my kubeconfig under a context named rpi-k8s, after backing up ~/.kube/config first. MicroK8s defaults call everything microk8s and admin, and I had an old microk8s context lying around from the bricked cluster. Renaming avoids pointing kubectl at the wrong cluster, which is a lesson you only want to learn once.

The Power-Cut Test

An always-on desk cluster should survive someone tripping over a power strip. So I rebooted all three nodes at once, the closest thing to a power cut I was willing to simulate. SSH came back after about 45 seconds and all three nodes were Ready with HA quorum after about 65. Kubelite had zero restarts, and DNS recovered without help.

A word from the wise: dqlite is a Raft-based datastore, so it needs a majority of voters. With three nodes you can lose one. Lose two and the API stops. The rule I now live by is one node at a time, and never take two down together. That rule gets written into the agent’s instructions later in this series.

The Weakest Link

All three nodes are on Wi-Fi. It works, but dqlite consensus and the pod network are latency sensitive, so Wi-Fi is the most likely cause of a flapping node. Ethernet is on my to-do list. Until then, this is a cluster for learning and light home use, not for anything you’d lose sleep over.

One more bit of prep: snap refreshes. By default every node would auto-refresh on its own schedule, so I staggered each node’s refresh window (Sunday 02:00, 03:30 and 05:00) so they never restart together. Combined with the 1.36 channel pin, that means only patch releases arrive, one node at a time.

Working with the Agent

So how did the build actually go? Here is the pattern, which held for the whole series. I type a request. The agent runs commands on the Pis over SSH, writes manifests and docs, and commits to Git. I decide scope, spend, and anything that touches Azure. When the agent is about to do something destructive or costly, it stops and asks.

Part 1 had a couple of nice examples of that split.

Version choice was mine. The agent started by following the Canonical guide to the letter and installed 1.30. Midway through, I interrupted: "if there is a more recent version of microk8s, we should be using that!" The agent purged it and reinstalled 1.36/stable. As a side effect, a Python LookupError: unknown encoding: ascii traceback appeared, from the old snap being removed underneath a running microk8s status. Harmless, but alarming for about three seconds.

The kernel problem was the agent’s to solve. It read the journal, worked out that the 6.18 kernel had no legacy ip_tables, found the nftables proxy mode, tried it on one node first and only then rolled it out. That is the same path I’d have taken myself, just with a lot less searching.

Sudo was my call too. The nodes needed a password for sudo, and I wasn’t going to hand my password to an agent. So I enabled passwordless sudo on the nodes myself, a trade-off I wrote down as a hardening item rather than pretending it isn’t one.

Where was it wrong? Its first instinct was to trust the 2024-era guide, and it didn’t think to question the channel until I pushed. It’s a good reminder that these tools read documentation like I do, which is to say confidently and sometimes a version behind. Part 9 digs into this properly, including the rules I eventually wrote down for it in an AGENTS.md file.

Wrapping Up

I now have a three-node MicroK8s 1.36 HA cluster on Raspberry Pi 4s that survives a simultaneous power cut, on the back of one kernel flag, a boot parameter and a pinned channel. That was the easy bit. In the next part I’ll move everything into Git with Flux and encrypt the secrets with SOPS, before the drift sets in.

As always, feel free to reach out with any questions or comments!

Up Next

  1. Rebuilding My Desk Kubernetes Cluster, Five Years On (this post)
  2. GitOps and Secrets with Flux and SOPS
  3. Workload Identity Without AKS
  4. Entra ID for kubectl, Five Years After Okta
  5. Ingress, Certificates and Getting Home Through CGNAT
  6. Hardening a Home Cluster, and How I Broke It
  7. Keeping It Patched Without Babysitting It
  8. One LLM Gateway for Everything, with a Hard $100 Cap
  9. What I Learnt Building It with an AI Agent

Until next time, stay cloudy!

Microsoft Agent 365: The Control Plane Your AI Agents Have Been Missing

Every organisation I’ve spoken to over the last few months has hit the same wall. They’ve built agents on Foundry, spun up a few in Copilot Studio, maybe even got a custom Python agent running somewhere on a VM that nobody quite remembers deploying. And now the questions are rolling in: how many agents do we actually have? What data can they access? Who’s responsible for them? Is anyone monitoring what they’re doing?

The agent sprawl is real, and Microsoft Agent 365 is Microsoft’s answer. Going GA on May 1 at $15 per user per month, it’s a unified control plane that treats AI agents like digital users, with the same governance, compliance, and security tooling you already use for your human workforce. Let’s dive in!

In English Please?

Agent 365 sits above your agent platforms. It doesn’t build or host agents. That’s what Foundry, Copilot Studio, and your own code are for. Instead, it provides a single pane of glass for discovering, governing, securing, and monitoring every agent in your tenant, regardless of where it was built or where it runs.

Think of it as the equivalent of what Entra ID does for human identities, but for AI agents. Every agent gets registered, policies are applied, compliance is enforced, and IT has full visibility. Whether you have 5 agents or 500, Agent 365 ensures they all follow the same rules.

The platform is organised around five pillars:

  • Registry: a centralised inventory of every agent in your tenant
  • Access Control: identity, conditional access, and lifecycle management via Entra Agent ID
  • Visualization: dashboards, agent maps, and usage analytics
  • Interoperability: governed access to M365 workloads via MCP servers
  • Security: threat protection via Defender, data security via Purview

If you’ve read my previous post on Entra Agent ID, Agent 365 is the governance layer that sits on top of it. Entra gives agents their identity; Agent 365 tells them what they’re allowed to do and watches what they actually do.

The Registry: Finding Your Shadow Agents

First cab off the rank, the Agent Registry. This is accessible from the Microsoft 365 Admin Center under Agents > All Agents, and it’s genuinely eye-opening.

The registry surfaces every agent in your tenant: Microsoft-built, partner-built, organisation-built, and critically, agents that nobody seems to own. For each agent you get:

  • Status and availability
  • Usage metrics (sessions, active users)
  • Exception rates
  • Last updated date
  • A Risks column that aggregates high-severity alerts from Entra, Purview, and Defender

That last column is gold. At a glance, you can see which agents are generating security alerts and need immediate attention.

There are a few admin capabilities I want to highlight:

Ownerless agent detection identifies agents whose creator has left the organisation. I’ve heard this from multiple customers. Agents still running months after their creator moved on, with nobody sure what they do or what data they access. Agent 365 flags these automatically and lets you reassign ownership or retire them.

Rules-based lifecycle policies let you automatically expire agents unused for 90 days, flag ownerless agents, or block agents marked as risky. Set it and forget it.

Export to Excel is simple, but critical for audit and compliance reporting. When your auditor asks “show me every AI agent in your environment,” you can hand them a spreadsheet in about three clicks.

The registry is also accessible programmatically via the Microsoft Graph API (currently in preview), using GET packages and GET package details endpoints. If you want to build your own dashboards or integrate agent inventory into your CMDB, that’s your path.

A word of caution though. As Jared Matfess from AvePoint noted after hands-on testing, the registry currently only surfaces published agents. In his tenant, Agent 365 showed 2 agents while the Power Platform admin center listed 47 in development. That’s a significant visibility gap for governance purposes. Third-party agent discovery is also manual; there’s no auto-discovery for agents running outside the Microsoft ecosystem. The vision is a complete inventory; the reality today is a partial one. Worth keeping in mind as you evaluate.

Governance with Purview: DLP, Retention, and the Risky Agents Template

This is where Agent 365 gets seriously interesting for compliance teams. It integrates directly with Microsoft Purview, and the coverage is comprehensive:

Purview Capability Supported
Data Loss Prevention (DLP) Yes
Sensitivity Labels Yes
Insider Risk Management Yes
Communication Compliance Yes
eDiscovery Yes
Data Lifecycle Management (retention) Yes
DSPM for AI (preview) Yes
Compliance Manager Yes
Auditing Yes

A few things that stand out:

DLP for agents: You can include agent instances in DLP policies just like users. Blocks and audits apply to agent-to-human and human-to-agent interactions across Teams, OneDrive/SharePoint, and email. If an agent tries to share a document marked “Highly Confidential” with an external user, DLP catches it. Same rules you already have for your human users, now applied to your AI agents.

The “Risky Agents” template: Insider Risk Management now has a dedicated policy template for AI agents. It detects agents exposed to risky prompts, agents generating sensitive responses, accessing priority SharePoint files, accessing risky websites, sharing files outside the organisation, and anomalous activity patterns. In my opinion, this is one of the most practical features in the entire platform. It takes the insider risk framework you already know and extends it to agents.

eDiscovery for agent interactions: Agent instances are searchable as mailbox sources. If legal needs to produce agent conversations for a matter, it works the same way as eDiscovering a user’s mailbox. This sounds boring until your legal team asks for it and you’re glad it exists.

Retention policies: Automatic retain-or-delete policies for agent interactions. Set your retention period, and Agent 365 handles it. Critical for organisations operating under regulatory retention requirements.

Threat Protection: Defender Integration

On the security side, Agent 365 integrates with Microsoft Defender for centralised threat detection and response. This goes beyond what we covered in the Content Safety post. This is runtime monitoring at the platform level.

What you get:

  • Out-of-the-box threat detections: alerts on risky agent activities surfaced in Defender XDR
  • Advanced hunting via KQL on the CloudAppEvents table, so your SOC team can query agent activity alongside all your other security signals
  • Security posture management: understand agent attack paths and remediate misconfigurations
  • Runtime defence: AI-powered blocking of prompt injection attacks and data exfiltration attempts in real time

Here’s a quick KQL example for hunting agent activity in Defender:

CloudAppEvents
| where ActionType in (
    "InvokeAgent",
    "InferenceCall",
    "ExecuteToolBySDK",
    "ExecuteToolByGateway",
    "ExecuteToolByMCPServer"
)
| summarize count() by ActionType, bin(Timestamp, 1h)
| order by Timestamp desc

If you’re already running Defender XDR, this is essentially free visibility into your agent estate. No new portal to learn.

The Developer Experience: SDK, CLI, and Blueprints

For developers building agents that need to play nicely with Agent 365 governance, Microsoft has shipped an SDK and CLI that adds enterprise capabilities to your existing agents.

Be warned: The SDK and CLI are currently in preview (you’ll need the --prerelease flag). But the developer experience is already pretty polished.

The CLI installs as a .NET global tool:

# Install the CLI
dotnet tool install --global Microsoft.Agents.A365.DevTools.Cli --prerelease

# Initialise configuration
a365 config init

# Full setup (registers blueprint, configures governance)
a365 setup all

# Deploy to Azure
a365 deploy

# Publish agent package to Agent 365
a365 publish

The SDK itself is available across .NET, Python, and JavaScript. Here’s how you’d add Agent 365 observability to an existing .NET agent using Semantic Kernel:

using Microsoft.Agents.A365.Observability;
using Microsoft.Agents.A365.Observability.Extensions.SemanticKernel;

var builder = WebApplication.CreateBuilder(args);

// Add Agent 365 tracing (OpenTelemetry-based)
builder.Services.AddAgenticTracingExporter();

// Auto-instrument Semantic Kernel
builder.Services.AddTracing(config => config.WithSemanticKernel());

The key concept for developers is Agent Blueprints. A blueprint is an IT-approved, pre-configured agent type definition that specifies capabilities, MCP tool access, security constraints, audit requirements, and linked governance policies (DLP, external access restrictions, logging rules). Think of it as a template that ensures every agent instance inherits consistent governance.

The workflow is: IT creates blueprints with approved configurations. Developers build agents from those blueprints. Every instance inherits the blueprint’s governance rules automatically. This gives developers the freedom to build while giving IT the guardrails they need. No more rogue agents with unrestricted access.

What Does It Cost?

The licensing model is worth understanding because it’s different from what you might expect:

  • $15 per user per month (standalone)
  • Included in Microsoft 365 E7 ($99/user/month), which bundles M365 E5 + Copilot + Entra Suite + Agent 365

The important bit: licensing is per user, not per agent. All agents acting on behalf of a licensed user are covered. So if you have 100 licensed users and 50 agents serving them, you pay for 100 user licenses, not 50 agent licenses. For organisations running lots of agents, this is a much more predictable cost model than per-agent pricing would have been.

Note: You need at least one Microsoft 365 Copilot license to access Agent 365, even in the standalone plan. This is a prerequisite, not a bundle.

Currently in Frontier preview, with GA on May 1, 2026. Frontier participants get 25 free licenses valid through December 2026.

I want to be transparent here: the community reaction to the pricing has been mixed. Gartner called Agent 365 “a work in progress with limited net new functionality to justify its $15 pupm price point.” Paul Robichaux at Office 365 IT Pros cautioned against rushing into the E7 bundle, noting that only about 3% of the M365 installed base currently uses Copilot. And a recurring question on the Tech Community forums is whether Agent 365 delivers genuinely new functionality or bundles existing Purview, Defender, and Entra capabilities under a new SKU.

My take? It’s a bit of both. The individual capabilities (DLP, Insider Risk, Conditional Access) already exist. What Agent 365 adds is the agent-aware glue: the registry, the blueprints, the lifecycle policies, and the agent-specific policy templates. Whether that’s worth $15/user/month depends on how many agents you’re running and how seriously your compliance team takes AI governance. For organisations with a handful of agents, it might be premature. For enterprises with dozens of agents across multiple platforms, the centralised visibility alone starts to justify it.

The Elephant in the Room: Is It Actually Unified?

I’d be doing you a disservice if I didn’t mention this. Despite being marketed as a “unified control plane,” the admin experience today still involves bouncing between the M365 Admin Center, Entra ID, Purview, and SharePoint Advanced Management. AvePoint’s assessment described it as a “swivel-chair” experience, and I think that’s fair. Agent 365 provides the policy framework and data model that ties everything together, but the day-to-day admin UX is still distributed across multiple portals.

Microsoft is clearly working towards a single-pane experience, and the M365 Admin Center’s Agents section is the starting point. But if you’re expecting a single console that handles everything from agent discovery to DLP policy authoring to threat investigation, that’s not quite where we are yet. Think of it as the control plane that connects existing admin surfaces, not (yet) one that replaces them.

As Precio Fishbone put it, Agent 365 is “an overlay, not a replacement.” I think that’s the right mental model.

Wrapping Up

Agent 365 fills what was, in my opinion, the biggest gap in Microsoft’s agentic story: governance at scale. We’ve had the tools to build agents (Foundry, Copilot Studio), secure their identities (Entra Agent ID), protect their interactions (Content Safety), and evaluate their behaviour (Foundry Evaluators). What we didn’t have was a single place to discover, govern, and monitor all of them. Now we do.

If you’re running more than a handful of agents in production, or planning to, I’d strongly recommend getting into the Frontier preview before GA hits in May. The registry alone is worth the effort, and the Purview integration means you can extend your existing compliance posture to cover AI agents without building anything new.

As always, feel free to reach out with any questions or comments!

Until next time, stay cloudy!